


- @wydyzq12


简介
该用户还未填写简介
擅长的技术栈
可提供的服务
暂无可提供的服务
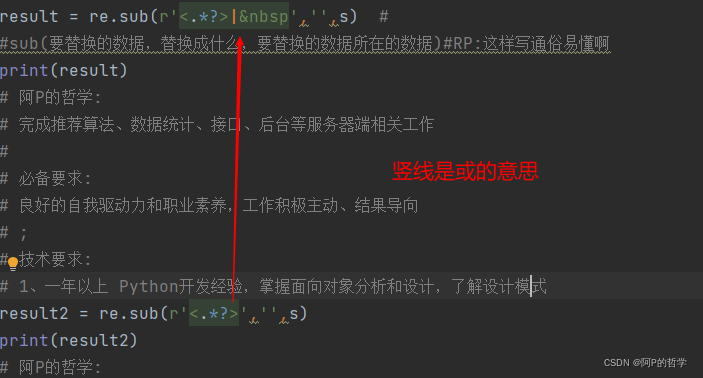
python里的数量词默认是贪婪的,总是尝试尽可能的匹配更多的字符。python中使用?号关闭贪婪模式如import reprint(re.match(r"aa\d+","aa2323"))#会尽可能多的去匹配\d# <re.Match object; span=(0, 6), match='aa2323'>print(re.match(r"aa\d+?","aa2323"))#尽可能
这主要是由于没有匹配到元素,之后又调用了group()方法造成的import recontent = 'hello world'result = re.match('^w.*d$', content)#这是想只提取worldprint(result)print(result.group())输出NoneTraceback (most recent call last):File "D:/000py
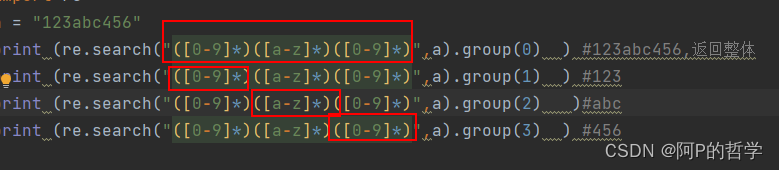
import rea = "123abc456"print re.search("([0-9]*)([a-z]*)([0-9]*)",a).group(0)#123abc456,返回整体print re.search("([0-9]*)([a-z]*)([0-9]*)",a).group(1)#123print re.search("([0-9]*)([a-z]*)([0-9]*)",a).gro
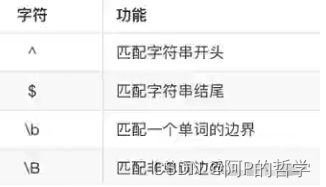
$ 匹配结尾字符定义整个字符串必须以指定字符串结尾import reprint(re.match('.*d$','2testaabcd')) #字符串必须以d结尾a=re.match('.*d$','2testaabcd')print(a.group())print(re.match('.*c$','2testaabcd'))#字符串不是以c结尾,返回noneb=re.match('.*c$','
一个\d代表一个数字。开头没匹配到,即使字符串其他部分包含需要匹配的内容,.match也会返回noneimport rea = re.match('\d\d','23es12testasdtest')print(a)print(a.group())b = re.match('\d\d\d','23es12testasdtest')print(b)#要求匹配三个数字,匹配不到返回nonec = re
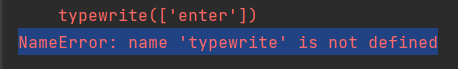
出现如图的提示是因为没有写入从属库名pyautogui
dm:today查询F盘扩展名是doc和jpg的文件,并且文件大小,大于1mb如果你想搜索某个类型的重复文件,只需在“dupe:”后加上该类型文件的后缀名即可,例如想要搜索重复的Word文档,则在Everything的搜索框中输入“dupe: *.doc”,然后回车即可。
可以直接将下面的代码添加到当前主题的 functions.php 文件即可。
pycharm使多行代码同时缩进鼠标选中多行代码后,按下Tab键,一次缩进四个字符