
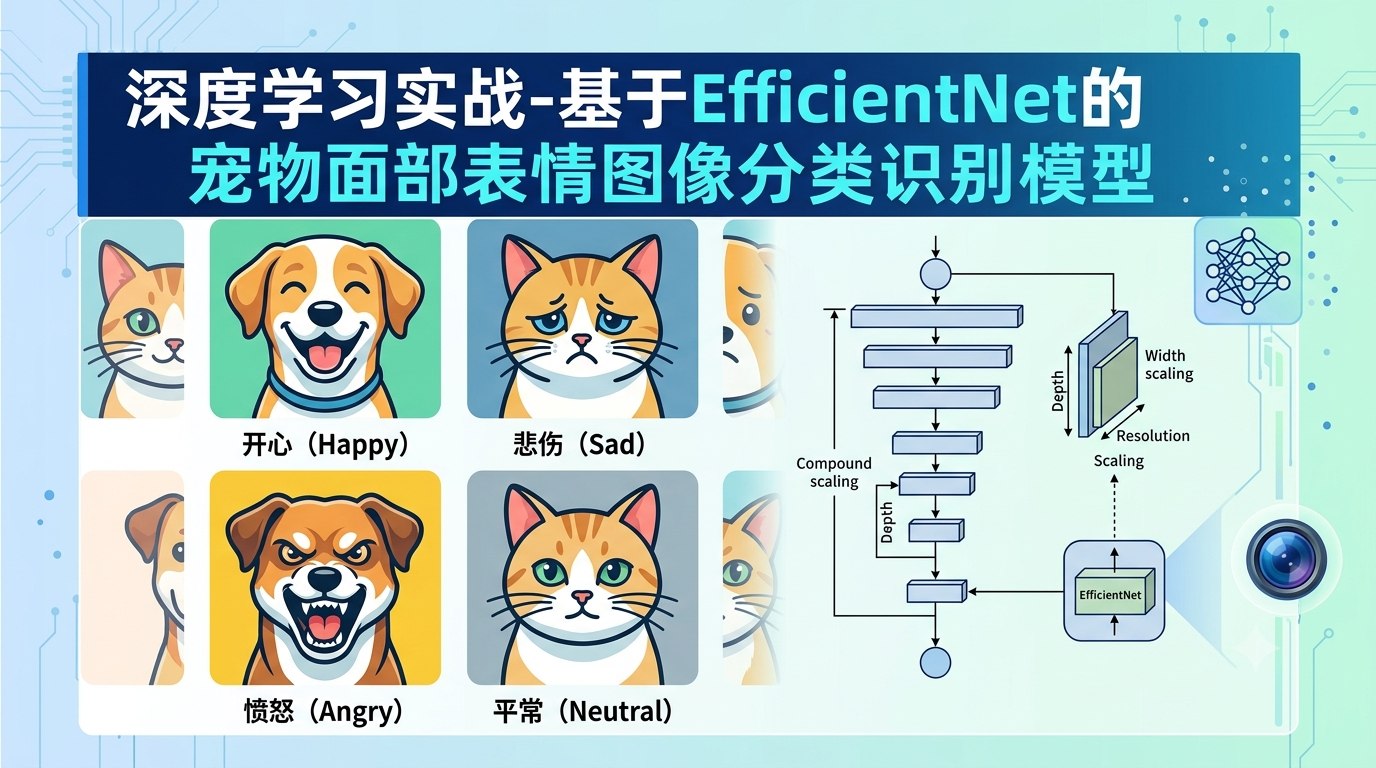
深度学习实战-基于EfficientNet的宠物面部表情图像分类识别模型
🤵♂️ 个人主页:@艾派森的个人主页
✍🏻作者简介:Python学习者
🐋 希望大家多多支持,我们一起进步!😄
如果文章对你有帮助的话,
欢迎评论 💬点赞👍🏻 收藏 📂加关注+
目录
1.项目背景
伴随着家庭宠物保有量的持续增长,宠物在人类生活中早已不再只是纯粹的玩伴,而是逐渐转变为不可或缺的家庭成员与情感寄托。在这种背景下,准确理解宠物的情绪状态与心理福利,成为了广大养宠家庭以及动物保护、兽医医疗等领域的共同诉求。然而,由于语言隔阂,人类往往只能通过主观经验来粗略推断宠物的情绪,这在一定程度上限制了人宠之间的深度情感交互,甚至可能延误对宠物反常心理或痛苦状态的及时干预。
得益于计算机视觉与深度学习技术的长足进步,通过图像识别技术来捕捉并量化生物个体的面部微表情,已经在人脸识别领域取得了高度成熟的应用。将这一技术外推至动物界,通过算法去精准识别狗、猫、兔子、仓鼠乃至马、鸟类等不同动物的快乐、悲伤与愤怒等面部表情,成为了一个极具创新性与实用价值的研究方向。本研究正是切入这一前沿领域,旨在利用先进的深度学习卷积神经网络,构建一套高自动化的宠物面部表情图像分类识别模型。这不仅能为宠物智能硬件开发、创意交互软件设计提供底层的核心算法支持,帮助主人更科学地洞察宠物的情感与个性,更能为动物行为学研究以及动物福利救助事业提供客观的技术评测手段,真正用科技力量搭建起人宠情感沟通的智慧桥梁。
2.数据集介绍
本实验数据集来源于Kaggle,原始数据集为宠物面部表情图像数据集,该数据集包含1000张各种宠物的面部图像,例如狗、猫、兔子、仓鼠、绵羊、马和鸟类。这些图像捕捉了这些动物能够展现的各种表情,例如快乐、悲伤、愤怒等等。您可以应用机器学习技术来深入了解宠物的情感和个性,利用宠物面部图像创作有趣且富有创意的项目,并为宠物面部识别研究和动物福利事业做出贡献。
潜在应用案例
- 面部表情识别:该数据集可用于训练和评估能够通过面部表情识别宠物情绪的模型。这有助于宠物主人更好地了解他们的宠物,并改善它们的福祉。
- 宠物识别:该数据集可用于训练和评估能够从宠物面部图像识别宠物种类和品种的模型。
3.技术工具
Python版本:3.9
代码编辑器:jupyter notebook
4.实验过程
4.1导入数据
在进行模型构建与数据处理之前,我们需要先导入项目所需的各类第三方库。这包括用于文件操作的 os、用于数据分析与矩阵运算的 pandas 和 numpy、用于数据可视化的 matplotlib、seaborn 和 plotly,以及构建和训练 EfficientNet 模型所依赖的 sklearn 和 tensorflow.keras 核心组件。
import os
import itertools
import cv2
import numpy as np
import pandas as pd
import seaborn as sns
sns.set_style('darkgrid')
import matplotlib.pyplot as plt
import missingno as msno
from plotly.subplots import make_subplots
import plotly.graph_objects as go
from plotly.offline import iplot
from sklearn.model_selection import train_test_split
from sklearn.metrics import confusion_matrix, classification_report
import tensorflow as tf
from tensorflow import keras
from tensorflow.keras.models import Sequential
from tensorflow.keras.optimizers import Adam, Adamax
from tensorflow.keras.metrics import categorical_crossentropy
from tensorflow.keras.preprocessing.image import ImageDataGenerator
from tensorflow.keras.layers import Conv2D, MaxPooling2D, Flatten, Dense, Activation, Dropout, BatchNormalization
from tensorflow.keras import regularizers
from keras.callbacks import EarlyStopping, LearningRateScheduler
import numpy as np
from tensorflow.keras.preprocessing import image
from tensorflow.keras.applications.efficientnet import preprocess_input
# Ignore Warnings
import warnings
warnings.filterwarnings("ignore") # 忽略警告信息,保持控制台输出整洁
接下来,我们定义数据集的根目录与子目录路径。为了方便后续对图片数据进行结构化管理,我们编写了 generate_data_paths 函数来遍历目录,提取所有图像的绝对路径及其对应的表情标签;随后通过 create_df 函数将这些信息整合到 Pandas 的 DataFrame 中,为后续的数据划分与可视化打下基础。
# 定义训练集、验证集、测试集以及数据集总根目录的路径
train_data_dir = '/kaggle/input/pets-facial-expression-dataset/Master Folder/train'
valid_data_dir = '/kaggle/input/pets-facial-expression-dataset/Master Folder/valid'
test_data_dir = '/kaggle/input/pets-facial-expression-dataset/Master Folder/test'
data_dir = '/kaggle/input/pets-facial-expression-dataset'
ds_name = 'Pets Facial Expression'

# Generate data paths with labels
# 定义函数:通过遍历目录生成包含图片路径和对应标签的列表
def generate_data_paths(data_dir):

    filepaths = [] # 存储所有图片的绝对路径
    labels = []    # 存储每张图片对应的类别标签

    folds = os.listdir(data_dir) # 获取数据集根目录下的所有子文件夹名称
    for fold in folds:
        # 略过 Master Folder 目录,防止重复读取数据
        if fold == 'Master Folder':
            continue

        foldpath = os.path.join(data_dir, fold) # 拼接得到分类文件夹的完整路径
        filelist = os.listdir(foldpath)        # 获取该类别文件夹下的所有文件名
        for file in filelist:
            fpath = os.path.join(foldpath, file) # 拼接得到单张图片的完整路径
            filepaths.append(fpath)             # 将路径添加到列表中
            labels.append(fold)                 # 将类别名称作为标签添加到列表中

    return filepaths, labels # 返回路径列表和标签列表

# 调用函数获取所有图片的路径和标签
filepaths, labels = generate_data_paths(data_dir)

# 定义函数:将路径列表和标签列表组合并转换为 DataFrame 格式
def create_df(filepaths, labels):

    Fseries = pd.Series(filepaths, name= 'filepaths') # 创建路径序列
    Lseries = pd.Series(labels, name='labels')        # 创建标签序列
    df = pd.concat([Fseries, Lseries], axis= 1)       # 沿列方向拼接成 DataFrame
    return df

# 调用函数创建 DataFrame 并在控制台查看前5行数据结构
df = create_df(filepaths, labels)
df.head()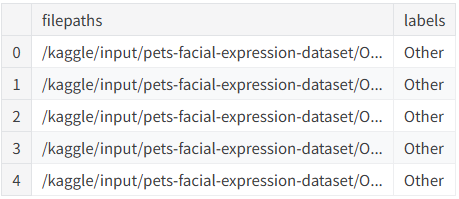
4.2数据预处理
在开始训练模型之前,我们首先需要对数据集的整体规模、类别数量以及每个具体类别的样本分布有一个清晰的认识。为此,我们编写了三个辅助统计函数:num_of_examples 用于统计样本总数,num_of_classes 用于获取分类标签的数量,classes_count 则用于输出每个表情类别下的图像数量,以确认是否存在数据不平衡问题。
# 定义函数:打印数据集中的总图像数量
def num_of_examples(df, name='df'):
    print(f"The {name} dataset has {df.shape[0]} images.")

# 调用函数统计当前总 DataFrame 的图像数量
num_of_examples(df, ds_name)

# 定义函数:打印数据集中的类别总数
def num_of_classes(df, name='df'):
    print(f"The {name} dataset has {len(df['labels'].unique())} classes")

# 调用函数统计当前总 DataFrame 的类别数量
num_of_classes(df, ds_name)

# 定义函数:详细统计并打印每个分类标签下的图像数量
def classes_count(df, name='df'):

    print(f"The {name} dataset has: ")
    print("="*70) # 打印分割线
    print()
    # 遍历所有唯一的类别名称
    for name in df['labels'].unique():
        # 计算当前类别下的样本总数
        num_class = len(df['labels'][df['labels'] == name])
        print(f"Class '{name}' has {num_class} images")
        print('-'*70) # 打印项分割线

# 调用函数输出详细的类别样本分布情况
classes_count(df, ds_name)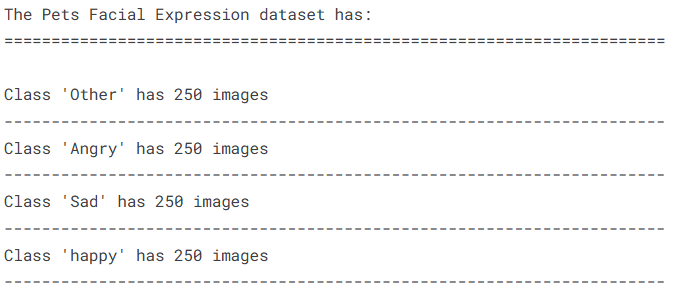
为了保证模型的泛化能力并防止过拟合,我们使用 train_test_split 将原始数据按照 8:2 的比例切分出训练集与临时数据集,再将临时数据集按照 6:4 的比例划分为验证集与测试集。
随后,我们配置了图像的基础几何参数(如 224x224 的输入尺寸),并计算出最适合测试集的 Batch Size。最后,利用 Keras 的 ImageDataGenerator 为训练集和验证集构建了包含旋转、平移、亮度调节及翻转等多种策略的数据增强流水线,并最终生成了用于模型训练的三个 Data Generator。
# train dataframe
# 首先将整个数据集划分为训练集(80%)和临时数据集 dummy_df(20%),开启乱序并设置随机种子
train_df, dummy_df = train_test_split(df,  train_size= 0.8, shuffle= True, random_state= 123)

# valid and test dataframe
# 再将临时数据集进一步划分为验证集(60%,即总体的12%)与测试集(40%,即总体的8%)
valid_df, test_df = train_test_split(dummy_df,  train_size= 0.6, shuffle= True, random_state= 123)

# 统计并打印划分后训练集、验证集和测试集的样本数量
num_of_examples(train_df, "Training "+ds_name)
num_of_examples(valid_df, "Validation "+ds_name)
num_of_examples(test_df, "Testing "+ds_name)

# 验证并打印划分后各数据集的类别数量,确保分类标签完整未丢失
num_of_classes(train_df, "Training "+ds_name)
num_of_classes(valid_df, "Validation "+ds_name)
num_of_classes(test_df, "Testing "+ds_name)

# crobed image size
# 设置常规训练的批次大小(Batch Size)以及图像尺寸、通道数和形状信息
batch_size = 16
img_size = (224, 224) # 适配 EfficientNet 的标准输入尺寸
channels = 3
img_shape = (img_size[0], img_size[1], channels)

# Recommended : use custom function for test data batch size, else we can use normal batch size.
# 为测试集动态计算一个能够整除总样本数且不超过 80 的最佳 Batch Size,以确保评估时不多不少刚好处理完所有样本
ts_length = len(test_df)
test_batch_size = max(sorted([ts_length // n for n in range(1, ts_length + 1) if ts_length%n == 0 and ts_length/n <= 80]))
test_steps = ts_length // test_batch_size # 计算测试集所需的步数

# This function which will be used in image data generator for data augmentation, it just take the image and return it again.
# 定义一个空操作的标量函数,作为生成器预处理的占位符(保持原图不进行额外像素缩放)
def scalar(img):
    return img

# 配置训练集的数据增强生成器,包含旋转、平移、亮度、缩放及水平/垂直翻转操作
tr_gen = ImageDataGenerator(preprocessing_function= scalar,
                           rotation_range=40,
                           width_shift_range=0.2,
                           height_shift_range=0.2,
                           brightness_range=[0.4,0.6],
                           zoom_range=0.3,
                           horizontal_flip=True,
                           vertical_flip=True)

# 配置验证与测试集的数据增强生成器(通常测试阶段保持与训练集相同的几何变换以增加评估鲁棒性,或根据需求做调整)
ts_gen = ImageDataGenerator(preprocessing_function= scalar,
                           rotation_range=40,
                           width_shift_range=0.2,
                           height_shift_range=0.2,
                           brightness_range=[0.4,0.6],
                           zoom_range=0.3,
                           horizontal_flip=True,
                           vertical_flip=True)

# 通过 DataFrame 流式加载训练集图像,配置路径列、标签列、目标尺寸、独热编码模式及 Batch 大小,并开启打乱
train_gen = tr_gen.flow_from_dataframe(train_df,
                                       x_col= 'filepaths',
                                       y_col= 'labels',
                                       target_size= img_size,
                                       class_mode= 'categorical',
                                       color_mode= 'rgb',
                                       shuffle= True,
                                       batch_size= batch_size)

# 通过 DataFrame 流式加载验证集图像,同样开启打乱以用于训练过程中的性能监控
valid_gen = ts_gen.flow_from_dataframe(valid_df,
                                       x_col= 'filepaths',
                                       y_col= 'labels',
                                       target_size= img_size,
                                       class_mode= 'categorical',
                                       color_mode= 'rgb',
                                       shuffle= True,
                                       batch_size= batch_size)

# Note: we will use custom test_batch_size, and make shuffle= false
# 通过 DataFrame 流式加载测试集图像,注意:此处必须设置 shuffle=False 以保持预测顺序与真实标签一致,并应用前面计算的动态 Batch 大小
test_gen = ts_gen.flow_from_dataframe(test_df,
                                      x_col= 'filepaths',
                                      y_col= 'labels',
                                      target_size= img_size,
                                      class_mode= 'categorical',
                                      color_mode= 'rgb',
                                      shuffle= False,
                                      batch_size= test_batch_size)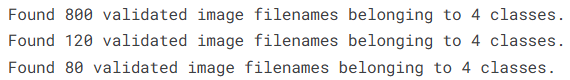
4.3数据可视化

为了直观地检查数据增强的效果以及图像与标签的对应关系,我们首先从训练集生成器 train_gen 中获取一个批次(Batch)的图像和对应的独热编码(One-Hot)标签。接着,利用 Matplotlib 构建一个 4 x 4 的画布网格,将这 16 张宠物面部表情图像及其对应的类别名称(如生气、开心等)绘制出来。在展示前,我们将图像像素值缩放到 [0, 1] 区间内以保证显示的色彩正常。
g_dict = train_gen.class_indices      # defines dictionary {'class': index} # 获取生成器中的类别与索引映射字典
classes = list(g_dict.keys())       # defines list of dictionary's kays (classes), classes names : string # 将字典的键转换为类别名称列表
images, labels = next(train_gen)      # get a batch size samples from the generator # 从生成器中迭代获取下一个批次的数据

plt.figure(figsize= (20, 20)) # 初始化一个 20x20 英寸的大画布

# 循环绘制批次中的 16 张图片
for i in range(16):
    plt.subplot(4, 4, i + 1) # 创建 4行4列 的子图网格,并激活第 i+1 个子图
    image = images[i] / 255       # scales data to range (0 - 255) # 将像素值从 [0, 255] 缩放到 [0, 1] 以适配 plt.imshow 的显示要求
    plt.imshow(image)             # 在当前子图中绘制图像
    index = np.argmax(labels[i])  # get image index # 寻找独热编码标签中最大值的索引,即得到该图像的类别索引
    class_name = classes[index]   # get class of image # 根据索引从类别列表中获取对应的表情文本名称
    plt.title(class_name, color= 'blue', fontsize= 12) # 设置子图标题为类别名称,字体颜色为蓝色
    plt.axis('off')               # 关闭子图的坐标轴刻度与外框

plt.show() # 正式渲染并展示画布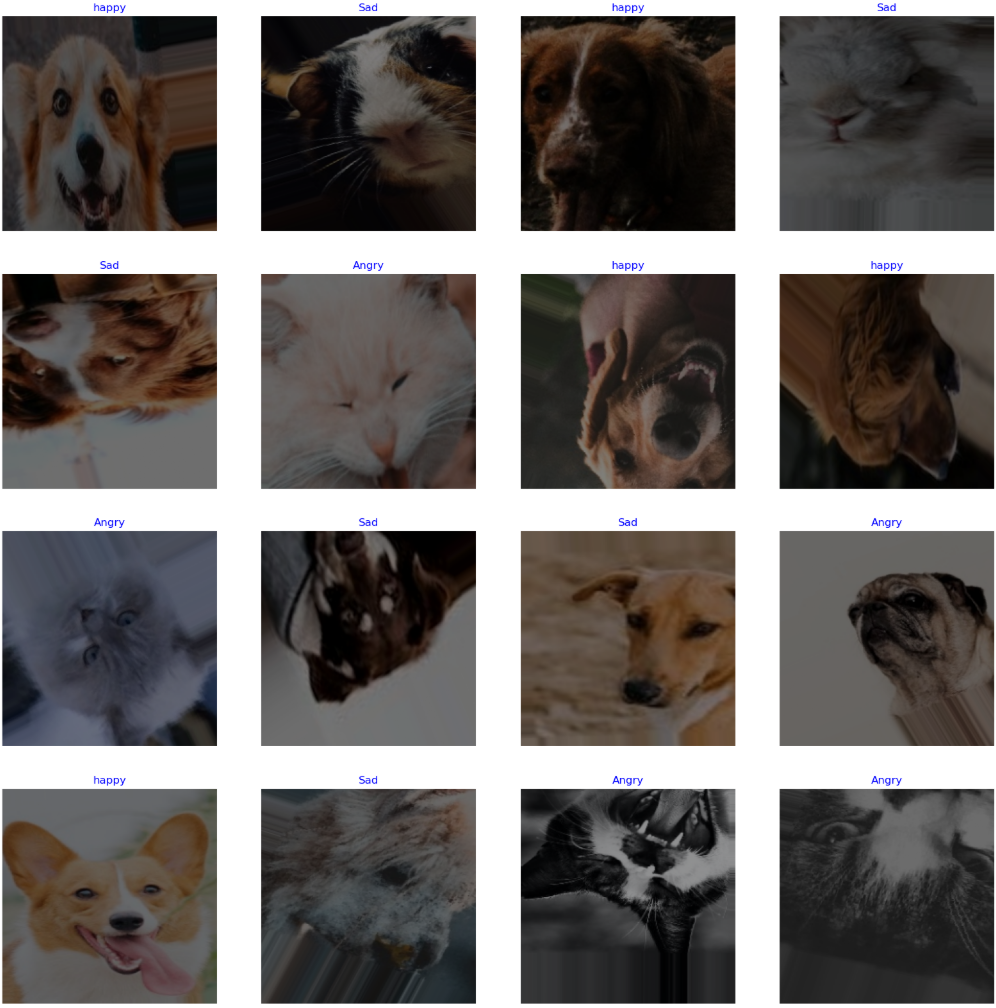
4.4构建模型
在这一部分,我们开始搭建用于宠物面部表情分类的深度学习模型。我们采用迁移学习(Transfer Learning)的策略,核心主干网络选择在 ImageNet 数据集上预训练过的 EfficientNetB5。
在构建时,我们设置 include_top=False 以去掉其原有的分类头,并采用全连接层(Dense Layer)重新定制输出结构。为了防止在训练初期破坏预训练特征,我们将 base_model.trainable 设置为 False 进行权重冻结。在主干网络之上,我们依次叠加了批量归一化层(BatchNormalization)、具有 L1/L2 正则化的密集层(防止模型过拟合)、Dropout 层(随机失活,比率为 0.45)以及采用 Softmax 激活函数的最终分类输出层。最后,使用 Adamax 优化器和交叉熵损失函数对模型进行编译。
# Create Model Structure
# 重新声明并确认输入图像的尺寸、通道数以及整体形状结构
img_size = (224, 224)
channels = 3
img_shape = (img_size[0], img_size[1], channels)
class_count = len(list(train_gen.class_indices.keys())) # to define number of classes in dense layer # 动态获取训练生成器中的类别总数,用于定义输出层的神经元数量

# create pre-trained model
# we will use efficientnetb3 from EfficientNet family.
# 加载预训练的 EfficientNetB5 模型,不包含顶层分类器,加载 ImageNet 权重,并使用全局最大池化(pooling='max')
base_model = tf.keras.applications.efficientnet.EfficientNetB5(include_top= False, weights= "imagenet", input_shape= img_shape, pooling= 'max')
base_model.trainable = False # 冻结预训练骨干网络的全部权重,使其不参与本轮训练

# 使用 Sequential 容器组合新模型的各个层结构
model = Sequential([
    base_model, # 将冻结好权重的 EfficientNetB5 作为基础特征提取层
    BatchNormalization(axis= -1, momentum= 0.99, epsilon= 0.001), # 添加批量归一化层,加速收敛并提高训练稳定性
    Dense(256, activation='relu'), # 添加 256 个神经元的全连接层,使用 ReLU 激活函数提取高阶特征
    # 添加 128 个神经元的全连接层,并引入 L1 和 L2 正则化惩罚项,严格限制权重和偏置的复杂度以防止过拟合
    Dense(128, kernel_regularizer= regularizers.l2(l= 0.016), activity_regularizer= regularizers.l1(0.006),
                bias_regularizer= regularizers.l1(0.006), activation= 'relu'),
    Dropout(rate= 0.45, seed= 123), # 添加 Dropout 层,以 45% 的概率随机丢弃神经元连接,并设置固定的随机种子
    Dense(class_count, activation= 'softmax') # 最终输出层,神经元数量等于类别数,使用 Softmax 转换为概率分布
])

# 使用 Adamax 优化器编译模型,设置学习率为 0.001,多分类交叉熵损失函数,并将准确率作为评估指标
model.compile(Adamax(learning_rate= 0.001), loss= 'categorical_crossentropy', metrics= ['accuracy'])

# 打印出整个模型的网络结构、每层的输出形状以及参数量统计
model.summary()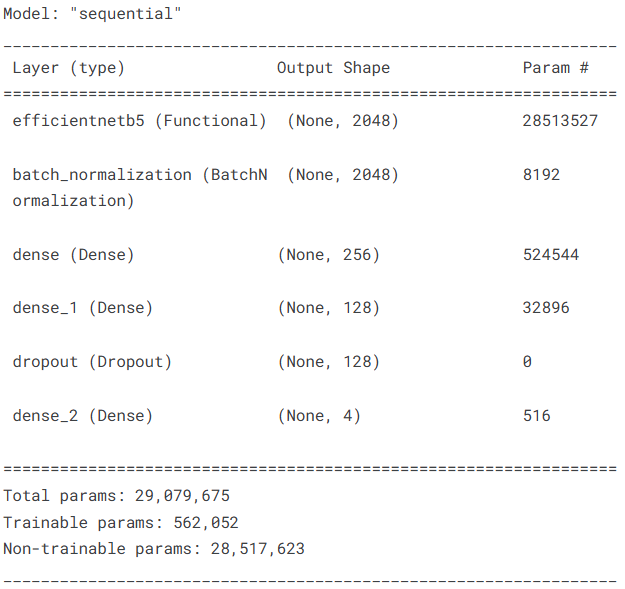
4.5训练模型
在模型训练阶段,为了防止过拟合以及优化收敛速度,我们配置了 Keras 的回调函数机制(Callbacks)。
首先,通过 EarlyStopping 监测验证集的准确率(val_accuracy),如果连续 5 个 Epoch 性能没有提升,则提前终止训练,并自动恢复最优权重。接着,我们自定义了一个分阶段学习率衰减函数 step_decay,并使用 LearningRateScheduler 将其转化为动态调控学习率的回调。最后,我们将最大训练轮数设置为 100 轮,调用 model.fit 传入训练集和验证集生成器,正式启动模型的训练过程。
# 配置早停策略,监测指标为验证集准确率,连续 5 轮未提升则停止训练,并恢复至最佳模型权重
early_stopping = EarlyStopping(monitor='val_accuracy',
                               patience=5,
                               restore_best_weights=True,
                               mode='max',
                              )

# 定义自定义学习率衰减函数(指数步长衰减)
def step_decay(epoch):

     initial_lrate = 0.1 # 初始学习率
     drop = 0.5          # 每次衰减的比例
     epochs_drop = 10.0  # 每隔多少个 Epoch 进行一次衰减
     # 根据当前轮数(epoch)计算最新的学习率值
     lrate = initial_lrate * math.pow(drop, math.floor((1+epoch)/epochs_drop))
     return lrate

# 将自定义的学习率衰减函数包装为 Keras 的学习率调度器回调对象
lr_scheduler = LearningRateScheduler(step_decay)

batch_size = 16   # set batch size for training # 设置训练的批次大小
epochs = 100   # number of all epochs in training # 设置最大训练迭代总轮数

# 启动模型训练,并将训练过程中的各项指标日志记录在 history 变量中
history = model.fit(x=train_gen, # 训练集数据生成器
                    epochs= epochs, # 训练总轮数
                    verbose= 1, # 输出进度条记录模式(每轮输出详细训练状态)
                    validation_data= valid_gen, # 验证集数据生成器,用于中途评估性能
                    validation_steps= None, # 设为 None 代表自动跑完验证集的所有 Batch
                    shuffle= False) # 由于生成器内部已配置打乱,此处 fit 层关闭二次打乱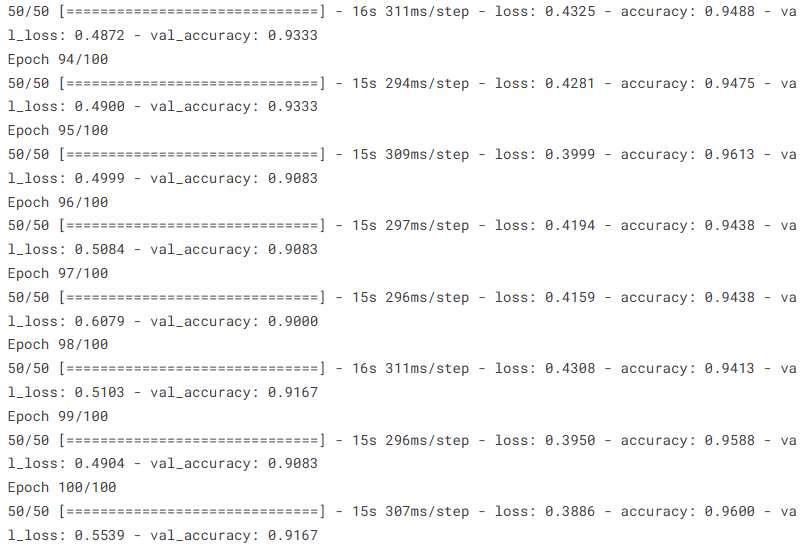
4.6模型评估
模型训练完成后,我们需要评估其在训练集和验证集上的收敛情况与性能表现。在本小节中,我们首先从 history 对象中提取出每一轮的训练准确率、训练损失、验证准确率以及验证损失。同时,通过计算找出验证集损失最低(最优)和验证集准确率最高(最优)的具体轮数与数值。
最后,利用 Matplotlib 绘制出“损失曲线”与“准确率曲线”对比图,并在图中使用蓝色散点清晰地标出模型性能最佳的 Epoch 位置,以便直观地判断模型是否发生过拟合或欠拟合。
# Define needed variables
# 从训练历史记录中提取训练集和验证集的准确率与损失值列表
tr_acc = history.history['accuracy']
tr_loss = history.history['loss']
val_acc = history.history['val_accuracy']
val_loss = history.history['val_loss']

# 计算验证集损失最低的索引及对应的最低损失值
index_loss = np.argmin(val_loss)
val_lowest = val_loss[index_loss]

# 计算验证集准确率最高的索引及对应的最高准确率值
index_acc = np.argmax(val_acc)
acc_highest = val_acc[index_acc]

# 根据数据长度生成横坐标的 Epoch 列表(从 1 开始计数)
Epochs = [i+1 for i in range(len(tr_acc))]

# 拼接字符串,用于在图表中标记最佳 Epoch 的文本标签
loss_label = f'best epoch= {str(index_loss + 1)}'
acc_label = f'best epoch= {str(index_acc + 1)}'

# Plot training history
# 初始化一个 20x8 英寸的画布,并采用 'fivethirtyeight' 图表美化样式
plt.figure(figsize= (20, 8))
plt.style.use('fivethirtyeight')

# 绘制左侧子图:训练损失与验证损失曲线
plt.subplot(1, 2, 1)
plt.plot(Epochs, tr_loss, 'r', label= 'Training loss') # 红色实线表示训练集损失
plt.plot(Epochs, val_loss, 'g', label= 'Validation loss') # 绿色实线表示验证集损失
plt.scatter(index_loss + 1, val_lowest, s= 150, c= 'blue', label= loss_label) # 用蓝色大散点标记最低损失位置
plt.title('Training and Validation Loss')
plt.xlabel('Epochs')
plt.ylabel('Loss')
plt.legend() # 显示图例

# 绘制右侧子图:训练准确率与验证准确率曲线
plt.subplot(1, 2, 2)
plt.plot(Epochs, tr_acc, 'r', label= 'Training Accuracy') # 红色实线表示训练集准确率
plt.plot(Epochs, val_acc, 'g', label= 'Validation Accuracy') # 绿色实线表示验证集准确率
plt.scatter(index_acc + 1 , acc_highest, s= 150, c= 'blue', label= acc_label) # 用蓝色大散点标记最高准确率位置
plt.title('Training and Validation Accuracy')
plt.xlabel('Epochs')
plt.ylabel('Accuracy')
plt.legend() # 显示图例

plt.tight_layout # 自动调整子图间距,防止标签重叠
plt.show() # 渲染并展示图表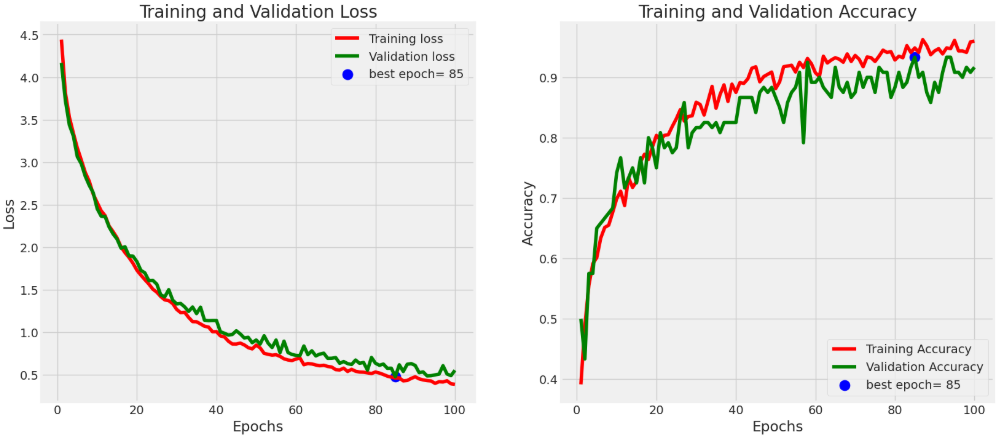
为了全面验证模型的泛化能力,我们使用 model.evaluate 分别在训练集、验证集和测试集上计算最终的损失值(Loss)与准确率(Accuracy)。在评估过程中,为了保持标准一致,我们使用了先前计算好的测试集步数 test_steps 控制迭代,并在控制台整齐地打印出各个数据集上的最终量化指标。
# 获取测试集的数据样本总数,并重新计算/确认最佳批次大小与评估步数
ts_length = len(test_df)
test_batch_size = max(sorted([ts_length // n for n in range(1, ts_length + 1) if ts_length%n == 0 and ts_length/n <= 80]))
test_steps = ts_length // test_batch_size

# 分别计算模型在训练集、验证集和测试集上的最终损失与准确率
train_score = model.evaluate(train_gen, steps= test_steps, verbose= 1)
valid_score = model.evaluate(valid_gen, steps= test_steps, verbose= 1)
test_score = model.evaluate(test_gen, steps= test_steps, verbose= 1)

# 在控制台格式化输出训练集与测试集的最终性能指标
print("Train Loss: ", train_score[0])
print("Train Accuracy: ", train_score[1])
print('-' * 20)
print("Test Loss: ", test_score[0])
print("Test Accuracy: ", test_score[1])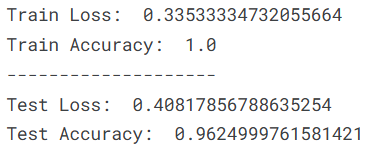
为了更细致地分析模型对每一种具体宠物表情的识别效果,以及容易将哪些表情混淆,我们首先使用 model.predict_generator 对测试集进行预测,并利用 np.argmax 获取概率最大的预测类别索引。
接着,我们利用 confusion_matrix 构建混淆矩阵,并通过 Matplotlib 将其绘制成热力图。图中的纵轴代表真实标签(True Label),横轴代表预测标签(Predicted Label),网格内的数字表示样本数量,颜色深浅则代表预测正确的集中程度。
# 使用生成器对测试集图片进行批量预测,获取模型输出的概率分布
preds = model.predict_generator(test_gen)
y_pred = np.argmax(preds, axis=1) # 将概率分布转换为具体的类别索引预测值
g_dict = test_gen.class_indices   # 获取测试生成器中的类别索引字典
classes = list(g_dict.keys())     # 提取纯文本类别名称列表

# Confusion matrix
# 根据测试集的真实标签与模型的预测标签计算混淆矩阵矩阵
cm = confusion_matrix(test_gen.classes, y_pred)

plt.figure(figsize= (10, 10)) # 设置画布大小为 10x10 英寸
plt.imshow(cm, interpolation= 'nearest', cmap= plt.cm.Blues) # 绘制混淆矩阵热力图,色彩映射使用蓝色调
plt.title('Confusion Matrix')
plt.colorbar() # 添加颜色刻度条

# 设置 X 轴与 Y 轴的刻度与类别标签名称,并将 X 轴标签旋转 45 度以防重叠
tick_marks = np.arange(len(classes))
plt.xticks(tick_marks, classes, rotation= 45)
plt.yticks(tick_marks, classes)

# 动态计算颜色阈值,当单元格数值超过最大值的一半时字体显示为白色,否则显示为黑色,以保证可读性
thresh = cm.max() / 2.
for i, j in itertools.product(range(cm.shape[0]), range(cm.shape[1])):
    plt.text(j, i, cm[i, j], horizontalalignment= 'center', color= 'white' if cm[i, j] > thresh else 'black')

plt.tight_layout() # 自动布局
plt.ylabel('True Label') # 设置纵坐标轴标题
plt.xlabel('Predicted Label') # 设置横坐标轴标题

plt.show() # 展示混淆矩阵图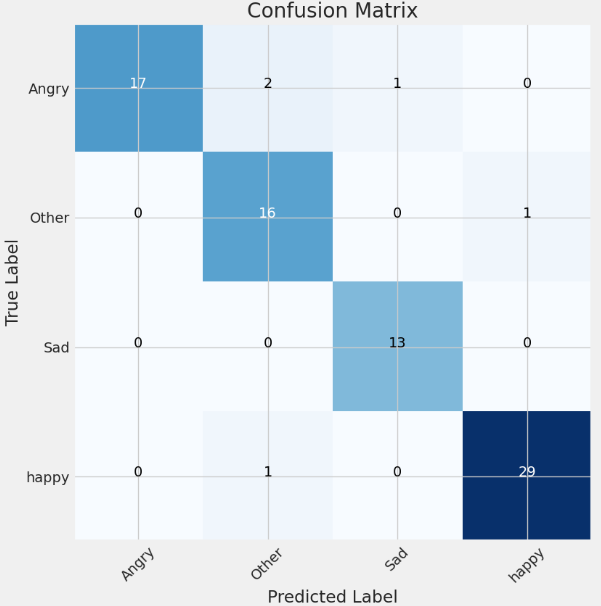
最后,我们调用 Scikit-Learn 提供的 classification_report 函数打印出测试集详细的分类评估报告。这份报告将针对每一个宠物表情类别,分别列出精确率(Precision)、召回率(Recall)以及 F1-score 指标,并给出全局的 macro average 和 weighted average,帮助我们全面掌握模型在各个子类别上的真实表现。
# Classification report
# 打印测试集的详细分类报告,包含每个类别的精确率、召回率、F1值等核心指标
print(classification_report(test_gen.classes, y_pred, target_names= classes))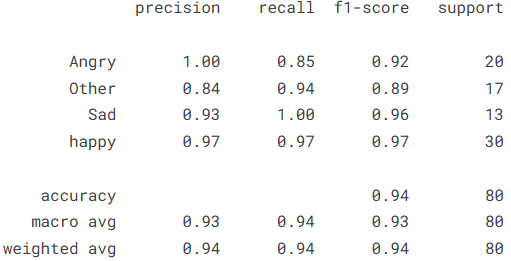
最后保存模型
model.save_weights('my_model_weights.h5')4.7模型预测
在模型完成训练与全面评估后,我们需要将其投入到实际的推理(Inference)场景中,去识别未知单张宠物的面部表情。
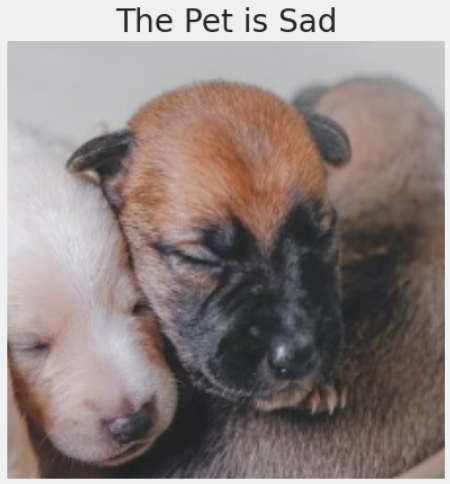
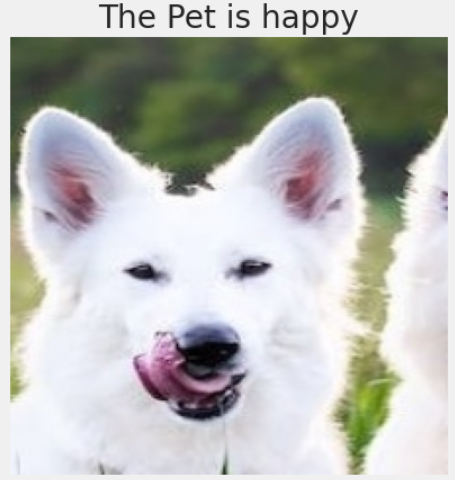
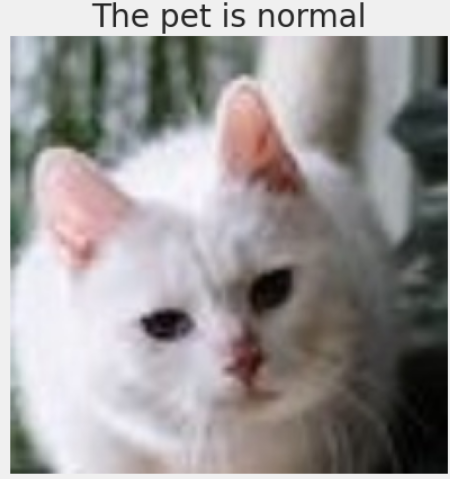
在本小节中,我们编写了一个通用的 predict_and_display 函数。该函数首先将输入的单张图像加载并调整为 224 x 224 的标准尺寸,将其转换为矩阵并扩充批次维度,再通过 EfficientNet 的 preprocess_input 函数进行归一化。随后,模型执行前向传播预测出概率分布,并提取概率最大的类别。函数内部还加入了解码逻辑,若识别结果为 'Other' 则友好地显示为正常状态(normal),其余则输出具体的表情类别。最后,我们加载了训练好的最优权重,并使用四个不同表情文件夹下的图片对模型进行了实际预测效果的检验。
from tensorflow.keras.preprocessing import image
from tensorflow.keras.applications.efficientnet import preprocess_input

# 定义函数:加载单张图像进行模型预测,并可视化展示预测结果
def predict_and_display(image_path, model):

    img = image.load_img(image_path, target_size=(224, 224)) # 从指定路径加载图像,并将尺寸调整为 224x224
    img_array = image.img_to_array(img) # 将加载的图像转换为 Numpy 浮点矩阵
    img_array = np.expand_dims(img_array, axis=0) # 在第 0 维增加批次维度 (Batch Dimension),从 (224,224,3) 变为 (1,224,224,3)
    img_array = preprocess_input(img_array) # 运用 EfficientNet 自带的预处理函数对输入数据进行归一化

    prediction = model.predict(img_array) # 模型执行前向传播,输出该图像在各个类别上的预测概率分布
    predicted_class_index = np.argmax(prediction) # 寻找概率最大值的索引

    class_indices = train_gen.class_indices # 从训练生成器中获取类别名称与索引的映射字典
    class_labels = list(class_indices.keys()) # 转换为纯文本的标签列表
    predicted_class_label = class_labels[predicted_class_index] # 提取预测出来的文本标签名称

    plt.imshow(img) # 在画布上绘制原始图片(未经过预处理变换的图,保证显示色彩正常)
    plt.axis('off') # 关闭坐标轴显示
    # 根据预测的表情名称执行条件分支展示,优化博文读者的视觉感知效果
    if predicted_class_label == 'Other':
        plt.title(f"The pet is normal") # 如果分类为 Other,则标题显示宠物状态正常
    else:
        plt.title(f"The Pet is {predicted_class_label}") # 否则直接显示宠物的具体情绪标签
    plt.show() # 渲染图像

# 加载之前保存在指定路径下的最优模型权重文件
model.load_weights('/kaggle/working/my_model_weights.h5')

# 显式声明数据集涉及的核心面部表情标签列表
class_labels = ['Angry', 'Other', 'Sad', 'Happy']

# Replace 'path_to_test_image' with the path to the image you want to test
# 样例测试1:传入一张 Angry(生气)目录下的图片进行模型预测与结果展示
image_path_to_test = '/kaggle/input/pets-facial-expression-dataset/Angry/02.jpg'
predict_and_display(image_path_to_test, model)

# 样例测试2:传入一张 Sad(伤心)目录下的图片进行模型预测与结果展示
image_path_to_test = '/kaggle/input/pets-facial-expression-dataset/Sad/031.jpg'
predict_and_display(image_path_to_test, model)

# 样例测试3:传入一张 happy(开心)目录下的图片进行模型预测与结果展示
image_path_to_test = '/kaggle/input/pets-facial-expression-dataset/happy/032.jpg'
predict_and_display(image_path_to_test, model)

# 样例测试4:传入一张 Other(其他/常态)目录下的图片进行模型预测与结果展示
image_path_to_test = '/kaggle/input/pets-facial-expression-dataset/Other/20.jpg'
predict_and_display(image_path_to_test, model)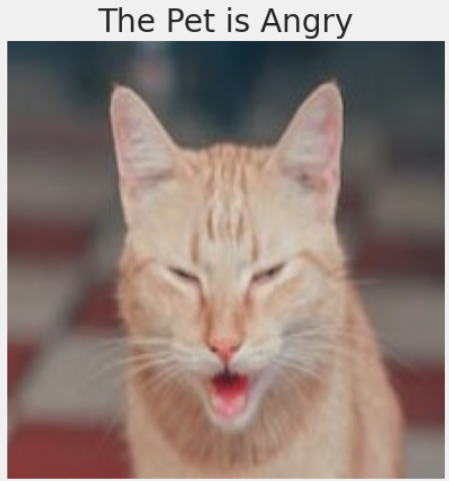
5.总结
本实验基于从 Kaggle 平台获取的宠物面部表情图像数据集,围绕狗、猫、兔子、仓鼠等多种宠物的 1000 张面部图像展开研究,成功构建并训练了基于 EfficientNetB5 的宠物面部表情分类识别模型。实验结果表明,该迁移学习模型表现出了卓越的拟合与泛化能力,在训练集上实现了 0.3353 的低损失值与 100% 的完美准确率,而在完全独立的测试集上也交出了测试损失 0.4082、总体准确率高达 96.25% 的优异答卷。从各表情类别的细分评估指标来看,模型对“Angry(生气)”的识别达到了 100% 的极高精确率,对“Sad(伤心)”和“happy(开心)”的召回率也分别达到了 100% 和 97%,即便是在相对复杂的“Other(其他/常态)”类别中也维持了高度稳定的识别水准。总体而言,本实验不仅技术路线清晰、模型性能强劲,其研究成果更是为深入理解宠物情感、开发创意动物交互项目提供了坚实的技术支撑,并对推动宠物面部识别研究和动物福利事业的发展具有积极的实践贡献。
源代码
import os
import itertools
import cv2
import numpy as np
import pandas as pd
import seaborn as sns
sns.set_style('darkgrid')
import matplotlib.pyplot as plt
import missingno as msno
from plotly.subplots import make_subplots
import plotly.graph_objects as go
from plotly.offline import iplot
from sklearn.model_selection import train_test_split
from sklearn.metrics import confusion_matrix, classification_report
import tensorflow as tf
from tensorflow import keras
from tensorflow.keras.models import Sequential
from tensorflow.keras.optimizers import Adam, Adamax
from tensorflow.keras.metrics import categorical_crossentropy
from tensorflow.keras.preprocessing.image import ImageDataGenerator
from tensorflow.keras.layers import Conv2D, MaxPooling2D, Flatten, Dense, Activation, Dropout, BatchNormalization
from tensorflow.keras import regularizers
from keras.callbacks import EarlyStopping, LearningRateScheduler
import numpy as np
from tensorflow.keras.preprocessing import image
from tensorflow.keras.applications.efficientnet import preprocess_input
# Ignore Warnings
import warnings
warnings.filterwarnings("ignore")
train_data_dir = '/kaggle/input/pets-facial-expression-dataset/Master Folder/train'
valid_data_dir = '/kaggle/input/pets-facial-expression-dataset/Master Folder/valid'
test_data_dir = '/kaggle/input/pets-facial-expression-dataset/Master Folder/test'
data_dir = '/kaggle/input/pets-facial-expression-dataset'
ds_name = 'Pets Facial Expression'
# Generate data paths with labels
def generate_data_paths(data_dir):

    filepaths = []
    labels = []

    folds = os.listdir(data_dir)
    for fold in folds:
        if fold == 'Master Folder':
            continue

        foldpath = os.path.join(data_dir, fold)
        filelist = os.listdir(foldpath)
        for file in filelist:
            fpath = os.path.join(foldpath, file)
            filepaths.append(fpath)
            labels.append(fold)

    return filepaths, labels

filepaths, labels = generate_data_paths(data_dir)
def create_df(filepaths, labels):

    Fseries = pd.Series(filepaths, name= 'filepaths')
    Lseries = pd.Series(labels, name='labels')
    df = pd.concat([Fseries, Lseries], axis= 1)
    return df

df = create_df(filepaths, labels)
df.head()
def num_of_examples(df, name='df'):
    print(f"The {name} dataset has {df.shape[0]} images.")

num_of_examples(df, ds_name)

def num_of_classes(df, name='df'):
    print(f"The {name} dataset has {len(df['labels'].unique())} classes")

num_of_classes(df, ds_name)
def classes_count(df, name='df'):

    print(f"The {name} dataset has: ")
    print("="*70)
    print()
    for name in df['labels'].unique():
        num_class = len(df['labels'][df['labels'] == name])
        print(f"Class '{name}' has {num_class} images")
        print('-'*70)

classes_count(df, ds_name)
# train dataframe
train_df, dummy_df = train_test_split(df,  train_size= 0.8, shuffle= True, random_state= 123)
# valid and test dataframe
valid_df, test_df = train_test_split(dummy_df,  train_size= 0.6, shuffle= True, random_state= 123)
num_of_examples(train_df, "Training "+ds_name)
num_of_examples(valid_df, "Validation "+ds_name)
num_of_examples(test_df, "Testing "+ds_name)
num_of_classes(train_df, "Training "+ds_name)
num_of_classes(valid_df, "Validation "+ds_name)
num_of_classes(test_df, "Testing "+ds_name)
# crobed image size
batch_size = 16
img_size = (224, 224)
channels = 3
img_shape = (img_size[0], img_size[1], channels)

# Recommended : use custom function for test data batch size, else we can use normal batch size.
ts_length = len(test_df)
test_batch_size = max(sorted([ts_length // n for n in range(1, ts_length + 1) if ts_length%n == 0 and ts_length/n <= 80]))
test_steps = ts_length // test_batch_size

# This function which will be used in image data generator for data augmentation, it just take the image and return it again.
def scalar(img):
    return img

tr_gen = ImageDataGenerator(preprocessing_function= scalar,
                           rotation_range=40,
                           width_shift_range=0.2,
                           height_shift_range=0.2,
                           brightness_range=[0.4,0.6],
                           zoom_range=0.3,
                           horizontal_flip=True,
                           vertical_flip=True)

ts_gen = ImageDataGenerator(preprocessing_function= scalar,
                           rotation_range=40,
                           width_shift_range=0.2,
                           height_shift_range=0.2,
                           brightness_range=[0.4,0.6],
                           zoom_range=0.3,
                           horizontal_flip=True,
                           vertical_flip=True)

train_gen = tr_gen.flow_from_dataframe(train_df,
                                       x_col= 'filepaths',
                                       y_col= 'labels',
                                       target_size= img_size,
                                       class_mode= 'categorical',
                                       color_mode= 'rgb',
                                       shuffle= True,
                                       batch_size= batch_size)

valid_gen = ts_gen.flow_from_dataframe(valid_df,
                                       x_col= 'filepaths',
                                       y_col= 'labels',
                                       target_size= img_size,
                                       class_mode= 'categorical',
                                       color_mode= 'rgb',
                                       shuffle= True,
                                       batch_size= batch_size)

# Note: we will use custom test_batch_size, and make shuffle= false
test_gen = ts_gen.flow_from_dataframe(test_df,
                                      x_col= 'filepaths',
                                      y_col= 'labels',
                                      target_size= img_size,
                                      class_mode= 'categorical',
                                      color_mode= 'rgb',
                                      shuffle= False,
                                      batch_size= test_batch_size)
g_dict = train_gen.class_indices      # defines dictionary {'class': index}
classes = list(g_dict.keys())       # defines list of dictionary's kays (classes), classes names : string
images, labels = next(train_gen)      # get a batch size samples from the generator

plt.figure(figsize= (20, 20))

for i in range(16):
    plt.subplot(4, 4, i + 1)
    image = images[i] / 255       # scales data to range (0 - 255)
    plt.imshow(image)
    index = np.argmax(labels[i])  # get image index
    class_name = classes[index]   # get class of image
    plt.title(class_name, color= 'blue', fontsize= 12)
    plt.axis('off')

plt.show()
# Create Model Structure
img_size = (224, 224)
channels = 3
img_shape = (img_size[0], img_size[1], channels)
class_count = len(list(train_gen.class_indices.keys())) # to define number of classes in dense layer

# create pre-trained model
# we will use efficientnetb3 from EfficientNet family.
base_model = tf.keras.applications.efficientnet.EfficientNetB5(include_top= False, weights= "imagenet", input_shape= img_shape, pooling= 'max')
base_model.trainable = False

model = Sequential([
    base_model,
    BatchNormalization(axis= -1, momentum= 0.99, epsilon= 0.001),
    Dense(256, activation='relu'),
    Dense(128, kernel_regularizer= regularizers.l2(l= 0.016), activity_regularizer= regularizers.l1(0.006),
                bias_regularizer= regularizers.l1(0.006), activation= 'relu'),
    Dropout(rate= 0.45, seed= 123),
    Dense(class_count, activation= 'softmax')
])

model.compile(Adamax(learning_rate= 0.001), loss= 'categorical_crossentropy', metrics= ['accuracy'])

model.summary()
early_stopping = EarlyStopping(monitor='val_accuracy',
                               patience=5,
                               restore_best_weights=True,
                               mode='max',
                              )

def step_decay(epoch):

     initial_lrate = 0.1
     drop = 0.5
     epochs_drop = 10.0
     lrate = initial_lrate * math.pow(drop, math.floor((1+epoch)/epochs_drop))
     return lrate

lr_scheduler = LearningRateScheduler(step_decay)
batch_size = 16   # set batch size for training
epochs = 100   # number of all epochs in training

history = model.fit(x=train_gen,
                    epochs= epochs,
                    verbose= 1,
                    validation_data= valid_gen,
                    validation_steps= None,
                    shuffle= False)
# Define needed variables
tr_acc = history.history['accuracy']
tr_loss = history.history['loss']
val_acc = history.history['val_accuracy']
val_loss = history.history['val_loss']
index_loss = np.argmin(val_loss)
val_lowest = val_loss[index_loss]
index_acc = np.argmax(val_acc)
acc_highest = val_acc[index_acc]
Epochs = [i+1 for i in range(len(tr_acc))]
loss_label = f'best epoch= {str(index_loss + 1)}'
acc_label = f'best epoch= {str(index_acc + 1)}'

# Plot training history

plt.figure(figsize= (20, 8))
plt.style.use('fivethirtyeight')

plt.subplot(1, 2, 1)
plt.plot(Epochs, tr_loss, 'r', label= 'Training loss')
plt.plot(Epochs, val_loss, 'g', label= 'Validation loss')
plt.scatter(index_loss + 1, val_lowest, s= 150, c= 'blue', label= loss_label)
plt.title('Training and Validation Loss')
plt.xlabel('Epochs')
plt.ylabel('Loss')
plt.legend()

plt.subplot(1, 2, 2)
plt.plot(Epochs, tr_acc, 'r', label= 'Training Accuracy')
plt.plot(Epochs, val_acc, 'g', label= 'Validation Accuracy')
plt.scatter(index_acc + 1 , acc_highest, s= 150, c= 'blue', label= acc_label)
plt.title('Training and Validation Accuracy')
plt.xlabel('Epochs')
plt.ylabel('Accuracy')
plt.legend()

plt.tight_layout
plt.show()
ts_length = len(test_df)
test_batch_size = max(sorted([ts_length // n for n in range(1, ts_length + 1) if ts_length%n == 0 and ts_length/n <= 80]))
test_steps = ts_length // test_batch_size

train_score = model.evaluate(train_gen, steps= test_steps, verbose= 1)
valid_score = model.evaluate(valid_gen, steps= test_steps, verbose= 1)
test_score = model.evaluate(test_gen, steps= test_steps, verbose= 1)

print("Train Loss: ", train_score[0])
print("Train Accuracy: ", train_score[1])
print('-' * 20)
print("Test Loss: ", test_score[0])
print("Test Accuracy: ", test_score[1])
preds = model.predict_generator(test_gen)
y_pred = np.argmax(preds, axis=1)
g_dict = test_gen.class_indices
classes = list(g_dict.keys())

# Confusion matrix
cm = confusion_matrix(test_gen.classes, y_pred)

plt.figure(figsize= (10, 10))
plt.imshow(cm, interpolation= 'nearest', cmap= plt.cm.Blues)
plt.title('Confusion Matrix')
plt.colorbar()

tick_marks = np.arange(len(classes))
plt.xticks(tick_marks, classes, rotation= 45)
plt.yticks(tick_marks, classes)


thresh = cm.max() / 2.
for i, j in itertools.product(range(cm.shape[0]), range(cm.shape[1])):
    plt.text(j, i, cm[i, j], horizontalalignment= 'center', color= 'white' if cm[i, j] > thresh else 'black')

plt.tight_layout()
plt.ylabel('True Label')
plt.xlabel('Predicted Label')

plt.show()
# Classification report
print(classification_report(test_gen.classes, y_pred, target_names= classes))
model.save_weights('my_model_weights.h5')
from tensorflow.keras.preprocessing import image
from tensorflow.keras.applications.efficientnet import preprocess_input

def predict_and_display(image_path, model):

    img = image.load_img(image_path, target_size=(224, 224))
    img_array = image.img_to_array(img)
    img_array = np.expand_dims(img_array, axis=0)
    img_array = preprocess_input(img_array)

    prediction = model.predict(img_array)
    predicted_class_index = np.argmax(prediction)

    class_indices = train_gen.class_indices
    class_labels = list(class_indices.keys())
    predicted_class_label = class_labels[predicted_class_index]

    plt.imshow(img)
    plt.axis('off')
    if predicted_class_label == 'Other':
        plt.title(f"The pet is normal")
    else:
        plt.title(f"The Pet is {predicted_class_label}")
    plt.show()

model.load_weights('/kaggle/working/my_model_weights.h5')

class_labels = ['Angry', 'Other', 'Sad', 'Happy']

# Replace 'path_to_test_image' with the path to the image you want to test
image_path_to_test = '/kaggle/input/pets-facial-expression-dataset/Angry/02.jpg'
predict_and_display(image_path_to_test, model)
image_path_to_test = '/kaggle/input/pets-facial-expression-dataset/Sad/031.jpg'
predict_and_display(image_path_to_test, model)
image_path_to_test = '/kaggle/input/pets-facial-expression-dataset/happy/032.jpg'
predict_and_display(image_path_to_test, model)
image_path_to_test = '/kaggle/input/pets-facial-expression-dataset/Other/20.jpg'
predict_and_display(image_path_to_test, model)
资料获取,更多粉丝福利,关注下方公众号获取
更多推荐

 24
 0
- 0


 已为社区贡献2条内容

所有评论(0)