
第2章:Spark集群安装与部署
前言
本章详细分析Spark运行模式的设计与实现, 重点介绍Spark的几种运行模式和原理,并分析了Spark和Yarn的结合。
一、Spark运行模式介绍
Spark以多种模式运行,可以在独立机器上以本地模式或伪分布式模式运行。 当集群以分布式模式运行时,底层资源调度可以使用Mesos或Yarn,也可以使用Spark的Standalone模式本身。 在每个模式之前,介绍一些基本概念和模型。
Spark runs in a variety of modes and can be run in either local mode or pseudo-distributed mode on a standalone machine. When running a cluster in a distributed mode, the underlying resource scheduling can either use Mesos or Yarn, or Spark’s Standalone mode itself. Before each pattern, introduce some basic concepts and models.
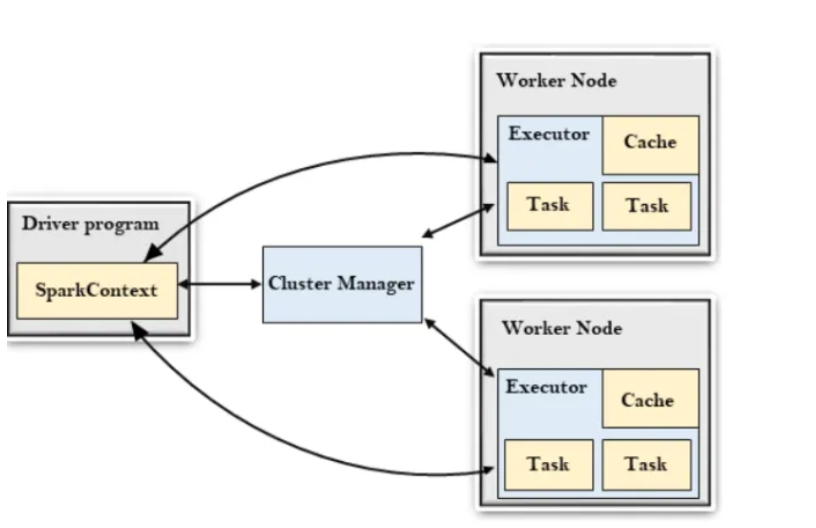
当Spark应用程序运行时,首先在Driver程序中创建Spark Context作为计划入口,并且在初始化期间创建**DAG Scheduler (Stage Scheduler)和Task Scheduler (Task Scheduler)**两个模块。
DAG Scheduler模块是一个基于阶段的调度模块,它为每个Spark Job计算具有依赖关系的多个阶段任务阶段,然后将每个阶段划分为一组特定的任务,并将它们以任务集的形式提交给底层task Scheduler模块以进行特定的执行。
Task Scheduler负责启动特定的任务,监控和报告任务的执行情况。 需要将运行任务所需的资源应用到Cluster Manager。
基本概念
1.Application
与Hadoop MapReduce类似,是一个用户编写的Spark应用程序,其中包含Driver函数和Executor代码,这些代码在集群中的多个节点上运行。
Similar to Hadoop MapReduce, is a user-written Spark Application that contains code for a Driver function and Executor code that runs across multiple nodes in a cluster.
2.Spark Driver
Spark中的驱动程序运行应用程序的main()函数并创建Spark上下文,为Spark应用程序准备运行环境。
The Driver in Spark runs Application’s main() function and creates Spark Context, which is created to prepare the running environment for the Spark Application.
3.Executor
应用程序在Worker节点上运行一个进程,该进程负责运行某些任务并将数据存储在内存或磁盘上。
An application runs a process on the Worker node that is responsible for running certain tasks and storing the data in memory or on disk.
4.Cluster Manager
指从集群中获取资源的外部服务。
Refers to external services that obtain resources on the cluster。
5.Worker
集群中可以运行应用程序代码的任何节点。
Any node in the cluster that can run the Application code.
6.Task
发送给执行者的工作单元是运行应用程序的基本单元。
the smallest unit of work that is sent to an Executor is the basic unit that runs the Application.
7.Job
并行计算由多个任务组成,由Spark Action触发。
Parallel computing, consisting of multiple tasks, is triggered by Spark Action.
8.Stage
每个作业被分成任务组作为任务集。
Each Job is split into groups of tasks as a Task Set.
9.RDD(重点! 后续会讲到)
Spark的基本单元,它可以通过一系列操作符进行操作。
Spark’s basic cell, which can be operated on through a series of operators.
10.Shared variables
当Spark应用程序运行时,您可能需要共享一些变量供Task或Driver使用。
When the Spark Application runs, you may need to share some variables for use by Task or Driver.
11.Shuffle Dependency
计算所有父RDD分区的数据,然后在节点之间运行Shuffle。
which requires that you calculate the data of all parent RDD partitions and then run Shuffle between nodes.
12.Narrow dependencies 窄依赖
Or Narrow Dependency, refers to a specific RDD.
13.DAG Scheduler
Builds a stage-based DAG based on Job and submits stages to the Task Scheduler.
基于Job构建基于阶段的DAG,并将阶段提交给Task Scheduler。
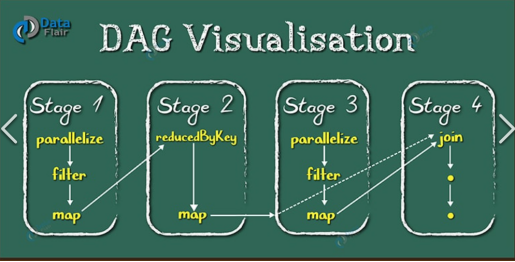
14.Task Scheduler
The Task Set is submitted to the Worker to run, where each Executor runs tasks.
任务集提交给Worker运行,其中每个Executor运行任务。
补充:Cluster Manager
在Apache Spark中,集群管理器是管理分布式机器集群中资源(如CPU和内存)的关键组件。它负责为Spark作业分配资源、在工作节点上启动执行器,并确保作业在集群中高效运行。本质上,集群管理器负责协调和调度构成Spark应用程序的各项任务。
In Apache Spark, the cluster manager is a crucial component that manages resources (such as CPU and memory) across a distributed cluster of machines. It is responsible for allocating resources to Spark jobs, launching executors on worker nodes, and ensuring that jobs run efficiently across the cluster. Essentially, the cluster manager handles the coordination and scheduling of tasks that make up a Spark application.
Cluster Manager的关键作用
1.Resource Allocation
集群管理器根据 Spark 应用程序的需求在整个集群中分配资源(例如 CPU、内存)。它确保资源得到有效分配,并且没有节点被过度或不足利用。
The cluster manager allocates resources (e.g., CPU, memory) across the cluster to Spark applications based on their requirements. It ensures that resources are distributed effectively and that no node is over- or under-utilized.
2.Task Scheduling
集群管理器在可用的工作节点上调度任务(单个工作单元)。它决定每个任务的运行位置,确保集群资源的最佳利用。
The cluster manager schedules tasks (individual units of work) on the available worker nodes. It decides where to run each task, ensuring optimal use of cluster resources.
3.Fault Tolerance:
如果任务或执行器失败,集群管理器负责在另一个节点上重新启动它,以确保 Spark 应用程序继续运行。
If a task or executor fails, the cluster manager is responsible for restarting it on another node to ensure that the Spark application continues running.
4.Executor Management
集群管理器启动执行器,这些执行器是运行在工作节点上的 **JVM 进程。**它还管理这些执行器的生命周期,确保在不再需要时将其终止。
The cluster manager launches executors, which are JVM processes that run tasks on worker nodes. It also manages the lifecycle of these executors, ensuring they are terminated when no longer needed.
5.Communication:
集群管理器促进了 Spark 驱动程序(负责协调作业的执行)与运行执行器的工作节点之间的通信。
The cluster manager facilitates communication between the Spark driver (which coordinates the execution of the job) and the worker nodes where executors run.
二、Spark运行模式
(一)local mode
1.定义
在单台机器上运行,适合开发和测试。
Runs on a single machine, suitable for development and testing
2.命令
To start shell = spark-shell (scala)
To start python shell = pyspark
To start spark sql = sparksql
To close shell = :quit
Spark job Web UI = ipaddress:4040 (niit01:4040)
(二)Standalone mode
1.定义
独立模式是 Spark 内置的集群管理器。在这种模式下,你可以通过启动一个主节点和多个工作节点来部署 Spark 集群。Spark 驱动程序可以运行在集群中的任何节点上,也可以在集群外运行。
在Spark独立集群中,对于每个应用程序,每个工作进程只能有一个执行器。
Standalone mode is Spark’s built-in cluster manager. In this mode, you can deploy a Spark cluster by starting a master node and multiple worker nodes. The Spark driver can run on any node in the cluster or outside the cluster.
2.命令
To start master and worker,Open spark directory
cd $SPARK_HOME
To start master and worker
sbin/start-all.sh
Master UI = ipaddress:8080 (niit:8080)
(Master UI:8080,Driver:4040)
3.运行特点
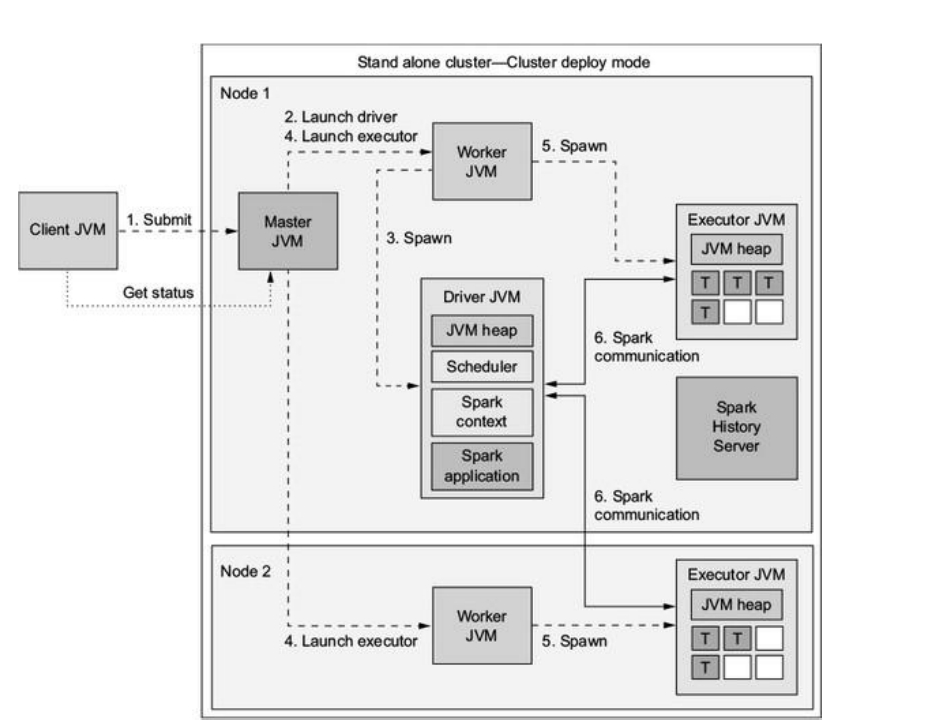
Spark独立集群运行在两个节点上,有两个worker:
1.客户端进程向主进程提交一个应用程序。
2. master指示其中一个worker启动一个驱动程序。
3. 工作线程生成一个驱动程序JVM。
4. 主进程指示两个worker为应用程序启动执行程序。
5. 工作者生成执行器jvm。
6. 驱动程序和执行程序独立于集群的进程进行通信。
Spark standalone cluster running on two nodes with two workers:
- A client process submits an application to the master.
- The master instructs one of its workers to launch a driver.
- The worker spawns a driver JVM.
- The master instructs both workers to launch executors for the application.
- The workers spawn executor JVMs.
- The driver and executors communicate independent of the cluster’s processes.
4.图例
如图所示,图中的驱动程序在集群中运行,换句话说,在集群部署模式下运行。 它还可以在客户机JVM中运行,这称为客户机-部署模式。
(1)Standalne-client模式提交任务:
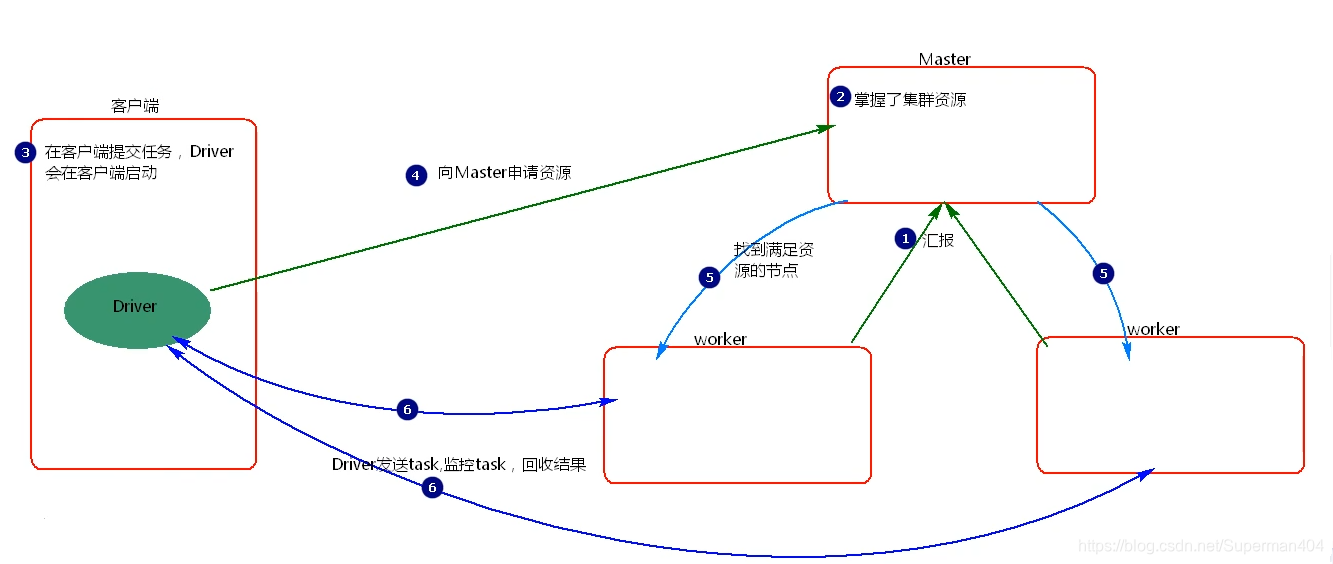
Standalne-client模式提交任务,会在客户端看到task的执行情况和结果。当客户端提交多个application时,每个application都会启动自己的Driver,Driver与集群worker有大量的通信,会造成客户端网卡流量激增的问题。这种模式适用于程序测试,不适用于生产环境
(2)Standalne-cluster模式提交任务:
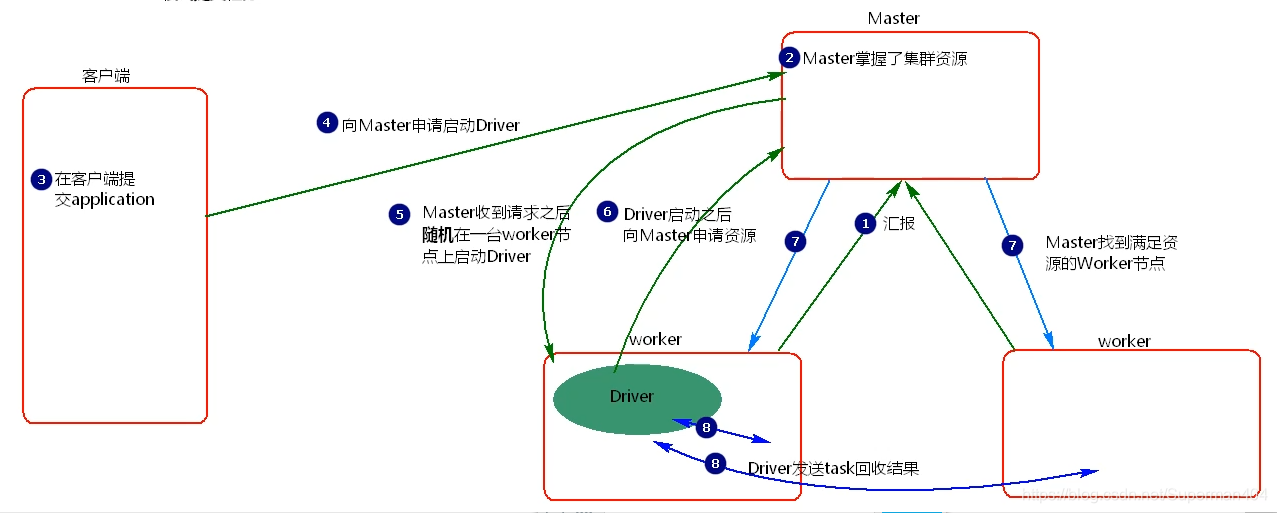
Standalne-cluster模式提交任务,Driver会在集群中的随机一台worker上启动,如果提交多个application,那么每个application的driver会分散到集群的worker节点,相当于将client模式的客户端网卡流量激增问题分散到集群中。这种模式适用于生产环境。
原文链接:https://blog.csdn.net/Superman404/article/details/84323054
(三)Spark Yarn-Cluster Model
1.介绍
在Yarn-Client模式下,驱动程序在客户端本地运行,这适用于应用程序本身需要本地交互的情况,如Spark Shell、Shark等,因为运行的结果可以直接获得。
在YARN中,主功能由各自的集群管理器(在YARN中是ResourceManager)提供,指的是YARN作为Spark应用程序的资源管理器的角色。
In YARN , the master functionality is provided by the respective cluster managers (ResourceManager in YARN) referring to YARN’s role as a resource manager for Spark application.
Spark中**“master”的概念指的是Driver**进程。在YARN集群模式下,Driver在YARN选择的一个节点上运行。
The concept of a “master” in Spark refers to the Driver process.
2.执行
Spark在YARN上可以运行两种子模式:客户端模式和集群模式。
(1)客户端模式 Client Mode
Spark驱动程序Driver运行在客户端机器上,执行程序运行在YARN集群上。
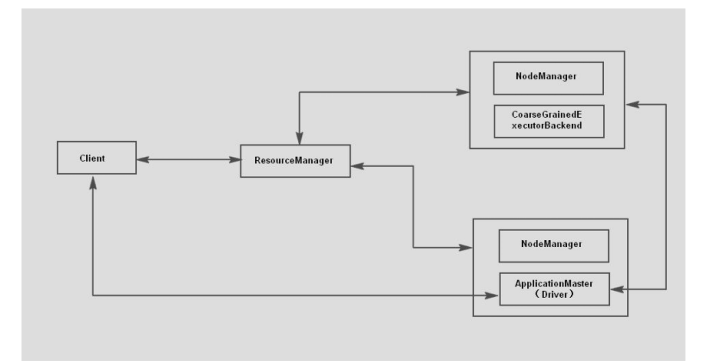
Yarn-Client部署:
SPARK_ EXECUTOR_ INSTANCES  # default:2
SPARK EXECUTOR CORES
SPARK EXECUTOR MEMORY
SPARK DRIVER MEMORY   #对应yarn中的AM
SPARK YARN APP NAME
SPARK_ YARN QUEUE
SPARK_ YARN DIST_ FILES #程序执行需要分发到每个ExecutorBackend的逗号分隔的文件列表中
SPARK_ YARN DIST_ ARCHIVES # 当程序执行时,需要将其分发到每个ExecutorBackend的ARCHIVES列表中,这些列表以逗号分隔
(2)集群模式 Cluster Mode
Spark驱动程序Driver在YARN集群内部,在其中一个工作节点上运行。
(四)Mesos mode
Apache Mesos是一个开源集群管理和资源调度平台,它提供了高效的资源隔离和跨分布式应用程序或框架的共享。从本质上讲,Mesos充当一个资源管理器,允许多个分布式应用程序(如Apache Spark, Hadoop, Kubernetes等)有效地共享相同的机器集群。它抽象底层硬件资源(CPU、内存、磁盘等),并允许应用程序以高度可伸缩、容错和分布式的方式运行。
1.描述
Mesos是一个集群管理器,可以运行各种分布式应用程序,包括Spark。在Mesos模式下,Spark应用程序与Mesos管理的其他框架共享集群资源。
Mesos is a cluster manager that can run various distributed applications, including Spark. In Mesos mode, Spark applications share cluster resources with other frameworks managed by Mesos.
2.执行
(1)Client Mode
驱动程序在客户端机器上运行,执行程序在mesos管理的节点上运行。
The driver runs on the client machine, and the executors run on Mesos-managed nodes.
(2)Cluster Mode
驱动程序在Mesos集群内的一个工作节点上运行。
The driver runs inside the Mesos cluster on one of the worker nodes.
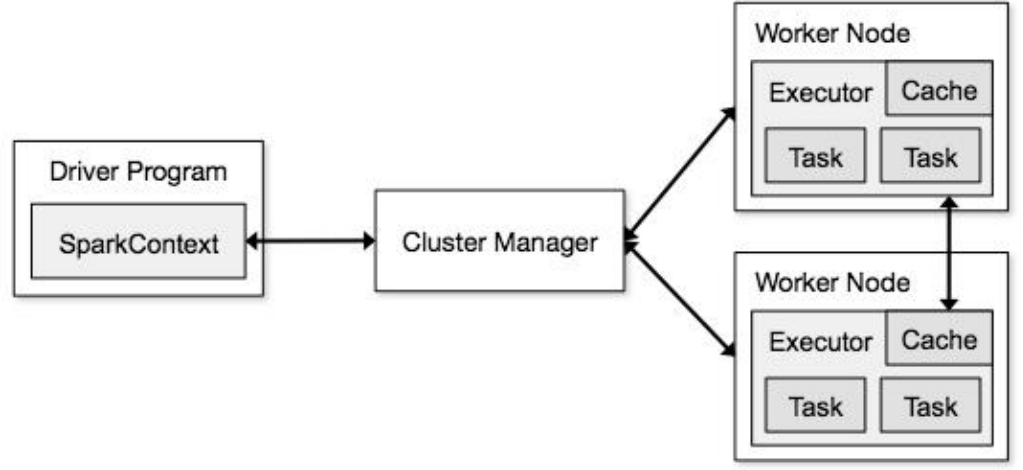
3.粗粒度与细粒度模式
(1)Coarse-Grained Mode
1.Mesos Master在Mesos slave(代理)上启动执行进程。
2.每个执行程序在启动时被分配固定数量的内核和内存。
3.这些执行器在Spark作业的整个持续时间内保持活动状态。
4.驱动程序将多个任务(来自不同的阶段)发送给执行器。
5.执行器一个接一个地执行任务→如果当前没有分配任务,则执行器处于空闲状态(但仍然消耗预留的资源)。
6.一旦所有任务完成并且作业结束,执行器将关闭,资源将被释放。
(2)Fine-Grained Mode
1.Mesos Master以非常小的块(每个任务级别)将Mesos slave的资源提供给Spark Driver。
2.驱动程序为每个单独的任务请求资源,而不是持有固定的执行程序。
3.Mesos直接在Mesos slave上的短期执行器容器中启动任务。
4.每个容器可能只运行一个或几个任务,并且在完成它们之后,它立即将资源释放回Mesos。
5.如果需要运行新的任务,驱动程序必须再次向Mesos请求新的资源,并且Mesos启动新的容器。
6.这允许多个框架(例如,Spark, Hadoop, Kafka)动态共享集群资源,因为一旦任务完成,资源就会被释放。
7.一旦所有任务都完成了,Spark应用程序就结束了,容器就不存在了。
总结
许多类型的Spark运行模式,每一种都以不同的方式实现。 本章详细分析Spark运行模式的设计与实现。 点介绍了Spark的几种运行模式和原理,并分析了Spark和Yarn的结合。
更多推荐

 15
 0
- 0


 已为社区贡献16条内容

所有评论(0)