
Chapter 4:RDD(非弹性分布式数据集)在spark中的作用
文章目录
- 前言
- 一、RDD是什么?
- (一)介绍
- 1.概念
- 2.特性
- (二)创建RDD
- 1.从集合中创建RDD
- 2.从外部数据集创建RDD
- 二、RDD的操作符
- (一)操作符的角色(Role of operators)
- 1. 输入 Input
- 2.操作 Operation
- 3.输出 output
- (二)SparkContext和SparkSession的区别
- (三)RDD的操作种类
- 1.转换(Transformation)
- (1)概念
- (2)类型
- 窄依赖 Narrow Transformations
- 宽依赖 Wide Transformations
- 2.动作(Action)
- 另:惰性计算的重要性
- (四)RDD的算子
- 1.transformation
- (1)Map
- (2)flatMap
- (3)Filter
- (4)Keys
- (5)Values
- (6)mapValues
- (7)ReduceByKey
- (8)GroupByKey
- (9)joins
- (10)Intersection 交集操作
- 2.actions
- (1)collect
- (2)First
- (3)take
- (4)Count
- (5)saveAsTextFile()
- 三、transformation和actions的比较
- 总结
前言
在集群的背后,有一个非常重要的分布式数据结构,这就是弹性分布式数据集(RDD)。 作为一个逻辑上集中的实体,它在集群中的多台机器上运行数据分区。 通过控制多台机器上不同的RDD分区,可以减少机器之间的数据变换。RDD是Spark的核心数据结构,通过RDD的依赖关系形成Spark的调度顺序。 RDD的操作构成了整个Spark程序。 本章的重点是RDD。
In Spark, all the data operations are nothing more than creating RDD, transforming RDD and calling RDD operations for evaluation. Behind the scenes, Spark automatically distributes data from RDD to clusters and parallelizes operations.
一、RDD是什么?
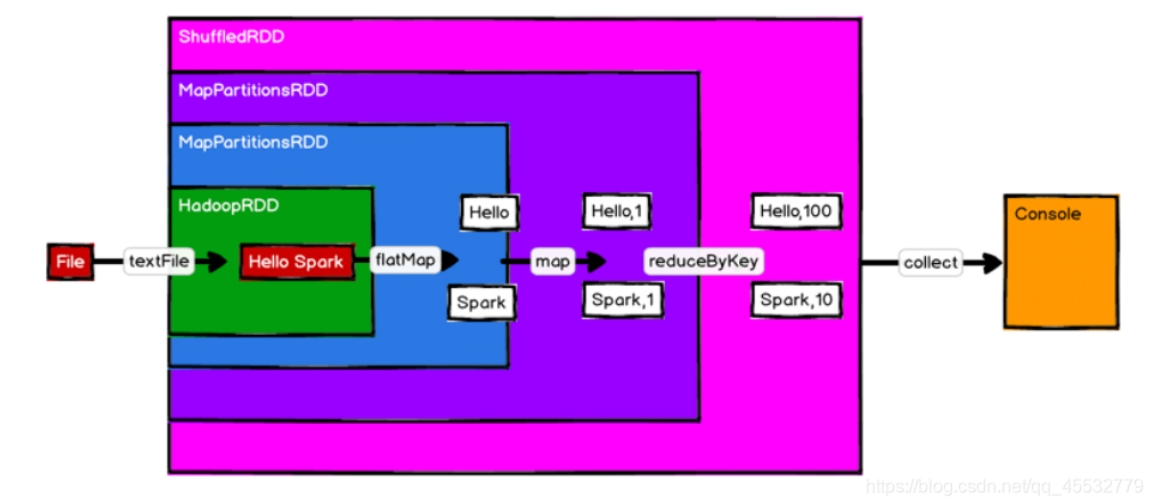
RDD(弹性分布式数据集)是Spark对数据的抽象。 事实上,RDD是分布式元素的集合。 在Spark中,所有的数据操作无非是创建RDD、转换RDD和调用RDD操作进行评估。 在后台,Spark自动将数据从RDD分发到集群,并并行化操作。
(一)介绍
1.概念
RDD(弹性分布式数据集)是Spark的核心底层抽象。RDD是一个不可变的、分区的元素集合,可以并行处理。它是弹性的,因为Spark可以使用RDD的沿袭(创建它的操作序列)重新计算丢失的分区。
RDD (Resilient Distributed Dataset) is Spark’s core low-level abstraction. An RDD is an immutable, partitioned collection of elements that can be processed in parallel. It is resilient because Spark can recompute lost partitions using the RDD’s lineage (the sequence of operations that created it).
分区:数据被分割成多个分区,执行器并行处理这些分区。每个分区由Task处理。
Partitioned: data is split into partitions that executors process in parallel.Each partition processed by Task.
2.特性
(1)RDD是只读的,一旦生成,内容就不能修改。 这样的优点是使得整个系统的设计相对简单,比如并行计算而不考虑数据排斥。
RDD is read-only, and once generated, the content cannot be modified, which has the advantage of
making the design of the entire system relatively simple, such as parallel computing without considering
data exclusion.
(2) RDD可以指定内存中的缓存。 通常,计算是在流中生成的,使用RDD。 生成新的RDD后,旧的RDD不再使用,由JVM回收。 但是,如果多个后续计算依赖于一个特定的RDD,我们可以在内存中缓存RDD以避免重复计算。 这个特性在迭代计算场景中特别有用,比如机器学习。
RDD can specify cache in memory. Generally, the computation is generated in stream, using RDD.
After the new RDD is generated, the old one is no longer in use and is recycled by the Java virtual
machine. But if multiple subsequent computations depend on a particular RDD, we can cache the RDD
in memory to avoid double-counting. This feature is particularly useful in iterative computing scenarios
such as machine learning.
(3) 可通过重新计算,计算RDD。 RDD的高可靠性不是通过复制实现的,而是通过记录足够的计算,以便在需要时从映像的重新计算或重新计算中恢复(例如:由于节点故障导致的内容失败)。
RDD can be calculated by recalculation. The high reliability of RDD is achieved not by copying, but by
recording enough computations to recover from re-computations or recalculations from an image if
needed (such as content failure due to node failure).
(二)创建RDD
创建RDD有两种方式
1.从集合中创建RDD
在驱动程序中演化一个集合,以从父RDD获得一个新的RDD。
Parallelize a local collection.
sc.parallelize(data)
val data = Seq (1, 2, 3, 4, 5)
val RDD = sc. Parallelize (data)

val data = Array (1, 2, 3, 4, 5)
val RDD = sc. Parallelize (data)

val data = List (1, 2, 3, 4, 5)
val RDD = sc. Parallelize (data)
2.从外部数据集创建RDD
从Hadoop文件系统(或其他兼容Hadoop的持久化存储系统,如Hive、Cassandra、HBase)(如HDFS)的输入中读取外部数据集并创建。
sc.textFile(datafile)
Read external data sets and create them from input from the Hadoop file system (or other Hadoop compatible persistent storage systems, such as Hive, Cassandra, HBase) (such as HDFS).
val lines = sc.textFile(“/path/README.md”)
二、RDD的操作符
(一)操作符的角色(Role of operators)
1. 输入 Input
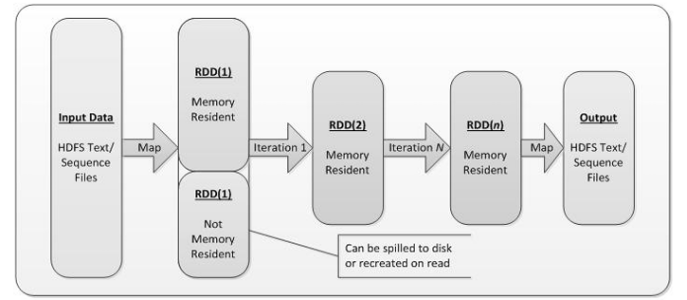
在Spark过程中,从外部数据空间(如分布式存储:textFile)HDFS等读取数据,并并行化方法将Scala集合或数据输入到Spark中,进入Spark运行时数据null,并在Spark中转换为数据块,通过BlockManager进行管理。
During Spark, data is read from external data space (such as distributed storage: textFile)HDFS, etc., and parallelize methods to enter Scala collections or data) into Spark, which goes into the Spark runtime data null and convert into data blocks in Spark for management through BlockManager.
2.操作 Operation
Spark数据输入形成RDD后,可以通过Filter等变换算子对数据进行操作。生成RDD并将其转换为新的RDD,然后触发Spark通过Action操作符提交作业。如果需要重用数据,可以使用Cache操作符将数据缓存到内存中。
After Spark data input forms RDD, data can be operated by transformation operator, such as Filter, etc. Make and convert RDD into the new RDD, and trigger Spark to submit the job through the Action operator. If the data needs to be reused, you can use the Cache operator to Cache the data into memory.
3.输出 output
程序运行端数据将输出Spark运行时空间并存储在分布式存储中(例如:SaveAsTextFile输出到HDFS,或Scala数据或集合(Collect输出到Scala集合,count返回Scala int data)。
(二)SparkContext和SparkSession的区别
| Feature | SparkContext | SparkSession |
|---|---|---|
| Introduction | Spark 1.x (older API) | Spark 2.0 (newer unified API) |
| Main Purpose | Entry point for working with RDDs (low-level API) | Entry point for DataFrames, Datasets, and SQL |
| Level of Abstraction | Lower-level (RDD-based operations) | Higher-level (DataFrame, Dataset, SQL-based operations) |
| Data Sources Supported | Limited to basic file formats (text, Hadoop) | Supports a wide variety of data sources (CSV, JSON, Parquet, ORC, Hive, etc.) |
| Ease of Use | More complex, requires manual RDD management | Simplifies data handling with DataFrames/Datasets |
| SQL Support | Not directly supported | Built-in SQL support (can run SQL queries) |
| Hive Support | Requires HiveContext | Built-in Hive support |
| DataFrame API | Not available | Primary focus on DataFrames/Datasets |
| Creation | val sc = new SparkContext(conf) | val spark = SparkSession.builder().appName("App").getOrCreate() |
| RDD Access | Yes | Yes, via spark.sparkContext |
| Deprecation | Still available but considered legacy | Preferred and modern way to interact with Spark |
(三)RDD的操作种类
RDD支持两种类型的操作:转换(从现有的数据中创建新的数据集) 和操作(在计算后将值返回给驱动程序的操作)。例如,映射是通过函数传递每个数据集元素并返回表示结果的新RDD的转换。另一方面,Reduce是一个操作,它使用一个函数来聚合RDD的所有元素,并将最终结果返回给驱动程序(尽管也有一个并行的Reduce By Key来返回分布式数据集)。
1.转换(Transformation)
(1)概念
从已有的RDD/DataFrame创建一个新的RDD/DataFrame的操作的操作。这些都是惰性计算(即,Spark构建DAG并仅在调用操作时执行它)。例如map、flatMap、filter和reduceByKey。而是构建一个转换计划(也称为有向无环图,DAG)。实际的执行只在Action被调用时才会发生。
Operations that create a new RDD from an existing one. These are lazy evaluated (i.e., Spark builds a DAG and executes it only when an action is called). Examples include map, flatMap, filter, and reduceByKey.
转换是不可变的。 它们不会修改已有的RDD或DataFrame,而是创建一个新的RDD或DataFrame。
Transformations are immutable. They do not modify the existing RDD or DataFrame but create a new one.
(2)类型
窄依赖 Narrow Transformations
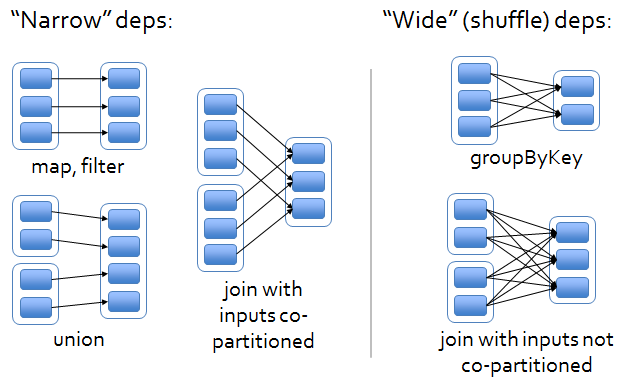
父RDD/DataFrame的每个分区最多只被子RDD/DataFrame的一个分区使用。一对一映射分区之间不需要混洗数据,这意味着数据不会在集群之间移动,使得这些转换更快、更高效。
Narrow transformations are those in which each partition of the parent RDD/DataFrame is used by at most one partition of the child RDD/DataFrame. There’s no need to shuffle data between partitions, meaning the data does not move across the cluster, making these transformations faster and more efficient.
实例:Map, filter, flatmap, map,partitions
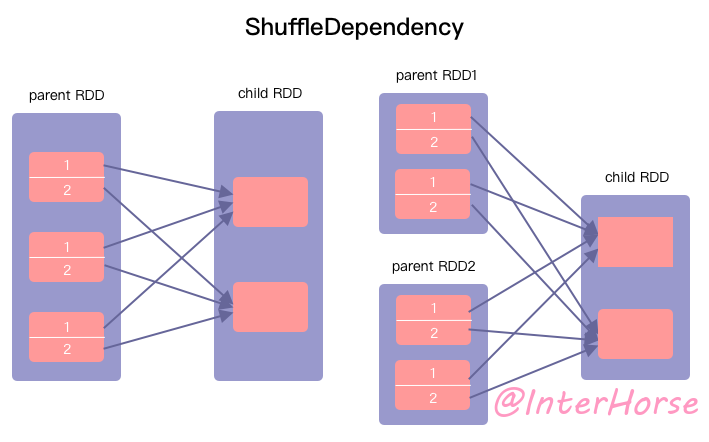
宽依赖 Wide Transformations
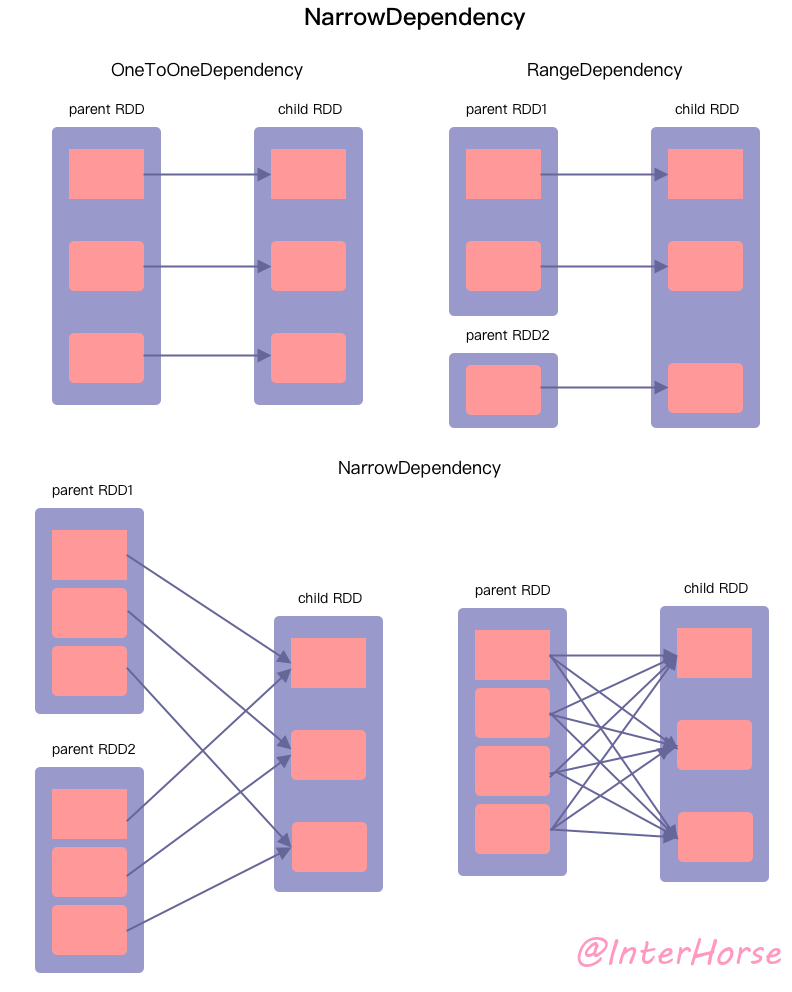
父RDD/DataFrame的多个分区中的数据需要被子RDD/DataFrame的一个或多个分区使用的情况。多对一映射这需要一个shuffle操作,数据会在集群中重新分布。混洗涉及磁盘I/O、网络I/O和排序,使得这些转换在时间和资源方面消耗更大。
Wide transformations are those where data from multiple partitions of the parent RDD/DataFrame is needed by one or more partitions of the child RDD/DataFrame. This requires a shuffle operation, where data is redistributed across the cluster. Shuffling involves disk I/O, network I/O, and sorting, making these transformations more expensive in terms of time and resources.
实例: GroupByKey, ReduceByKey, join
2.动作(Action)
触发执行并将结果返回给驱动程序或存储数据的操作。 例如:collect、count和saveAsTextFile。
Operations that trigger execution and return a result to the driver or store the data. Examples are collect, count, and saveAsTextFile.
另:惰性计算的重要性
惰性求值允许Spark通过重排序或合并操作来优化执行计划,从而减少数据的传递次数,减少计算时间。
Lazy evaluation allows Spark to optimize the execution plan by reordering operations or combining operations, minimizing the number of passes over the data and reducing computation time.
(四)RDD的算子
1.transformation
(1)Map
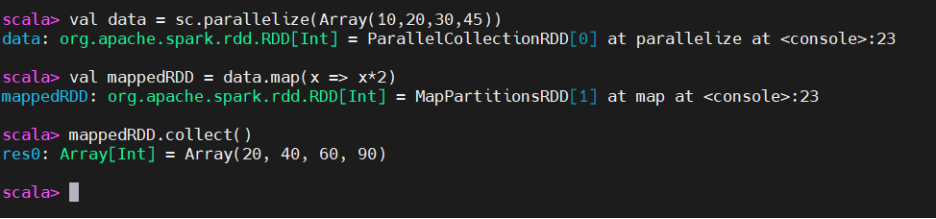
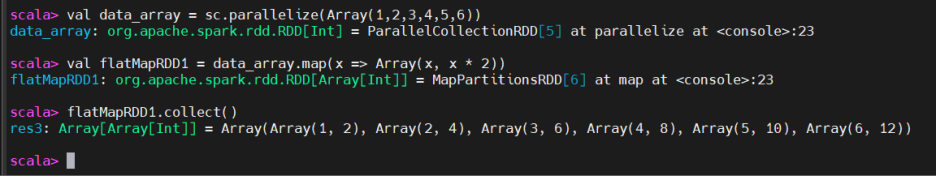
转化操作map()对RDD(或DataFrame)中的每个元素应用一个函数,并返回一个包含结果的新RDD。这是一个一对一的转换,意味着对于每个输入元素,只有一个输出元素。
输出不是扁平的;它保留了输入RDD或DataFrame的结构
The map() transformation applies a function to each element in the RDD (or DataFrame) and returns a new RDD with the results. It is a one-to-one transformation, meaning for each input element, there is exactly one output element.
The output is not flattened; it retains the structure of the input RDD or DataFrame
(2)flatMap
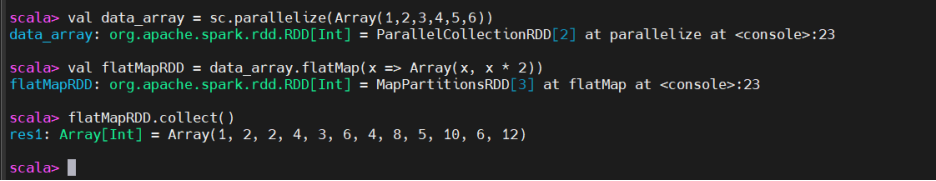
flatMap()转换方法与map()类似,但它允许为每个输入元素返回多个值。它将结果扁平化,这意味着输出是一个单层集合。
The flatMap() transformation is similar to map(), but it allows returning multiple values for each input element. It flattens the results, meaning the output is a single-level collection.The output is flattened into a single collection
(3)Filter
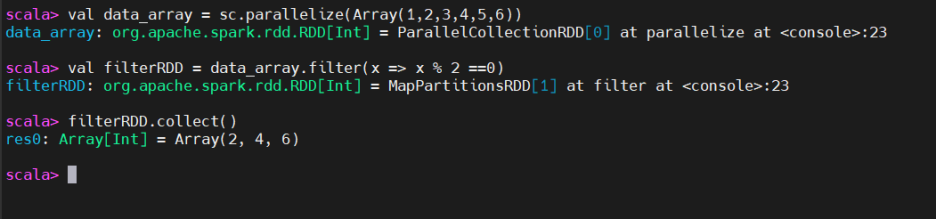
转化操作filter()返回一个只包含满足给定条件的元素的新RDD。它用于根据某些条件过滤元素。
当需要根据特定条件过滤数据时,可以使用filter()。
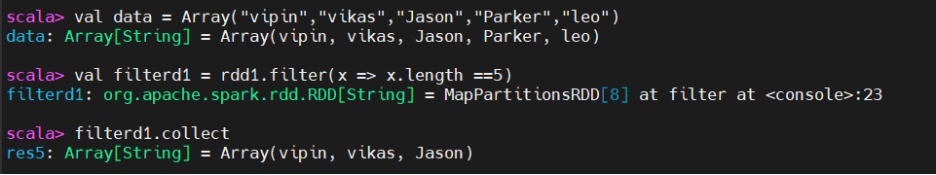
如果字符长度超过5,就过滤掉:
如果word以“vi”开头,则返回结果,否则删除它。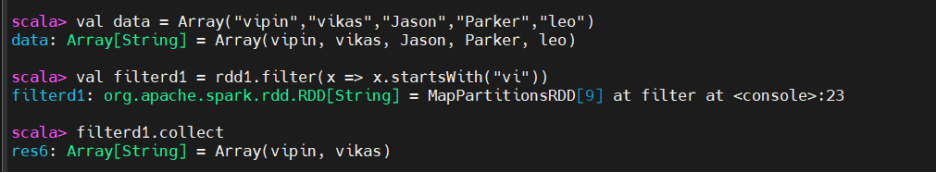
(4)Keys
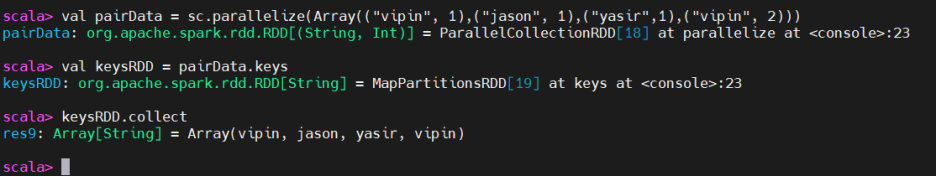
keys只会返回键值对中 RDD中的键,从而形成一个新的RDD。
(5)Values
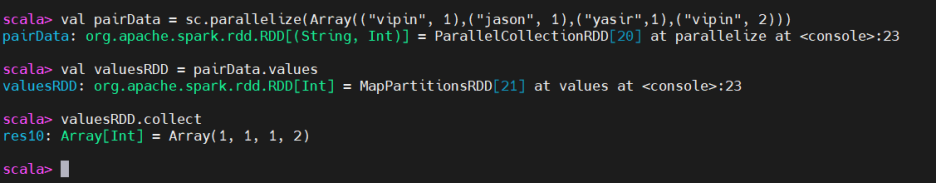
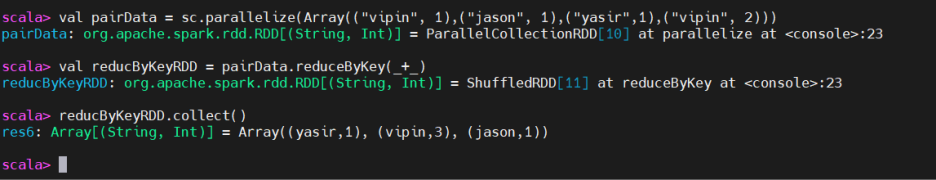
values只会返回RDD键值对中的值,形成一个新的RDD。
(6)mapValues
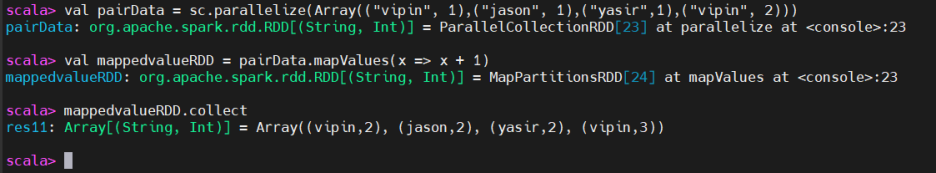
mapValues()函数只对键值对的值进行操作,同时保留键的值。
下面进入宽依赖
(7)ReduceByKey
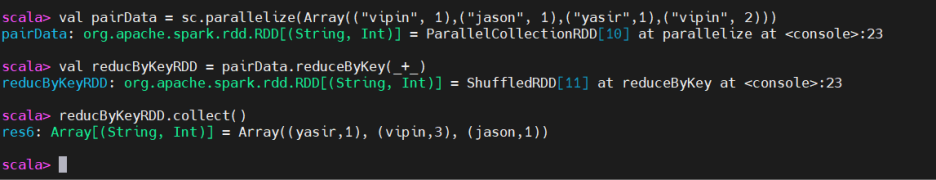
reduceByKey()转换函数使用指定的二元运算(如加法或乘法)来组合每个键对应的值。它首先在本地执行归约操作,然后将归约后的值在集群中进行混洗以得到最终结果。在聚合方面,它比groupByKey()更高效。
当需要聚合每个键的值时,可以使用reduceByKey()
(8)GroupByKey
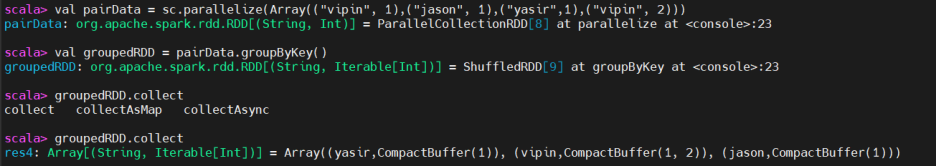
groupByKey()将数据按键分组,返回一个由(K, Iterable[V])对组成的RDD,其中K是键,Iterable[V]包含与该键相关联的所有值。该操作涉及跨集群的数据混洗,以按键对值进行分组。
当需要将每个键的所有值分组在一起时,可以使用groupByKey()。
(9)joins
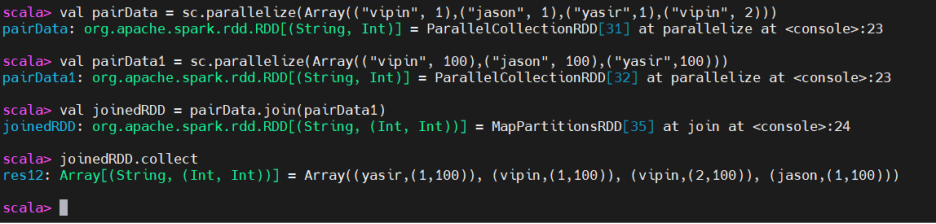
join()用于根据键合并两个键值对RDD。这类似于SQL的内联结(INNER JOIN),只有两个数据集中匹配的键才包含在结果中。
(10)Intersection 交集操作
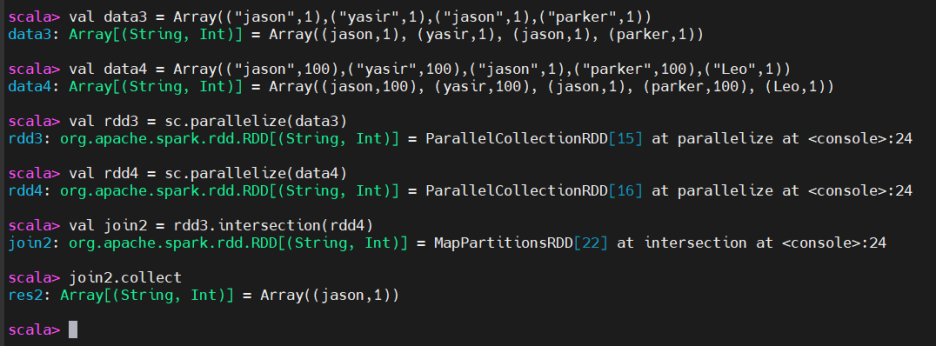
Apache Spark中的交集变换(intersection transformation)用于找到两个rdd (Resilient Distributed dataset,弹性分布式数据集)或dataframe之间的公共元素。
交集操作将同时匹配键和值。
2.actions
动作触发已定义的转换的执行。当一个action被调用时,Spark会处理转化操作,并将结果返回给驱动器程序,或者将其写入外部存储系统(例如HDFS)。
Actions trigger the execution of the transformations that have been defined. When an action is called, Spark processes the transformations and returns the result to the driver or writes it to an external storage system (e.g. HDFS).
(1)collect
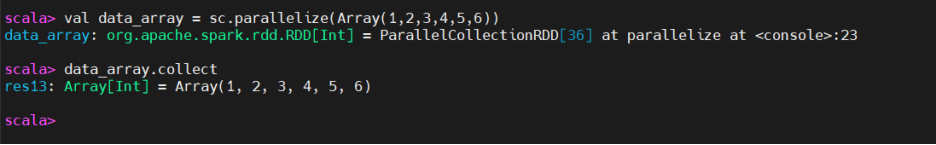
collect是从分布式集群中将整个数据集(RDD或DataFrame)以数组或集合的形式获取到驱动器程序中。
当你想在本地查看或处理整个数据集时,通常需要使用collect。
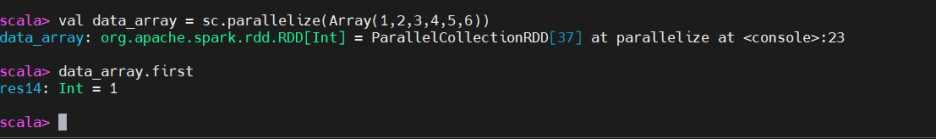
(2)First
first()是一个行动操作,返回RDD或DataFrame的第一个元素。
first() is an action that returns the first element of an RDD or DataFrame.
(3)take
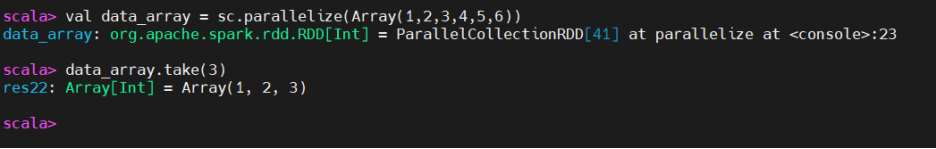
take(n)是一个行动操作,返回RDD或DataFrame中的前n个元素。
(4)Count
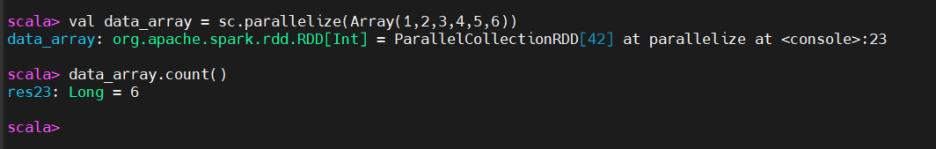
count()是一个行动操作,用于返回RDD或DataFrame中元素的个数。
(5)saveAsTextFile()
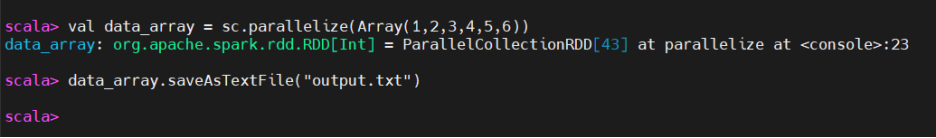
saveAsTextFile()是一个操作,它将RDD(或DataFrame)的内容以一系列文本文件的形式写入目录。RDD的每个分区都以单独的文本文件的形式保存在指定的目录中。
当需要将输出存储到外部文件系统(如HDFS、本地磁盘)以供进一步使用或分析时,可以使用saveAsTextFile()。
三、transformation和actions的比较
| Feature (特征) | Transformations (转换) | Actions (动作) |
|---|---|---|
| Definition (定义) | Define a new RDD from an existing one (从现有RDD定义新的RDD) | Trigger computation and return a result (触发计算并返回结果) |
| Lazy Evaluation (惰性求值) | Yes, evaluated lazily (是的,惰性求值) | No, they trigger the actual execution (不,它们触发实际执行) |
| Return Type (返回类型) | Returns a new RDD (返回一个新的RDD) | Returns a value or exports data (to file, driver, etc.) (返回值或将数据导出到文件、驱动程序等) |
总结
本章重点讲解了非弹性分布式数据集RDD在spark中的作用以及操作符的分类,各种算子的使用方法。特别是对于宽依赖和窄依赖的区分,要清楚熟记。
更多推荐

 37
 0
- 0


 已为社区贡献16条内容

所有评论(0)