
【Kubernetes 1.33.7 安装部署】
·
BUG
error execution phase wait-control-plane: failed while waiting for the control plane to start: [kube-controller-manager check failed at https://127.0.0.1:10257/healthz: Get “https://127.0.0.1:10257/healthz”: dial tcp 127.0.0.1:10257: connect: connection refused, kube-apiserver check failed at https://192.168.235.128:6443/livez: client rate limiter Wait returned an error: rate: Wait(n=1) would exceed context deadline, kube-scheduler check failed at https://127.0.0.1:10259/livez: Get “https://127.0.0.1:10259/livez”: dial tcp 127.0.0.1:10259: connect: connection refused]To see the stack trace of this error execute with --v=5 or higher
# Check current sandbox image in containerd config
grep sandbox_image /etc/containerd/config.toml

# It should show:
# sandbox_image = "registry.aliyuncs.com/google_containers/pause:3.10"

# If not, update it:
sed -i 's#sandbox_image = ".*"#sandbox_image = "registry.aliyuncs.com/google_containers/pause:3.10"#g' /etc/containerd/config.toml

# Restart containerd
systemctl restart containerd
# Reset kubeadm
kubeadm reset -f --cri-socket=unix:///run/containerd/containerd.sock

# Clean up
rm -rf /etc/kubernetes/
rm -rf /var/lib/kubelet/
rm -rf /etc/cni/net.d/
iptables -F && iptables -t nat -F && iptables -t mangle -F && iptables -X
ipvsadm --clear

# Restart services
systemctl restart containerd
systemctl restart kubelet
# Ensure sufficient resources
free -h  # At least 2GB RAM recommended
df -h    # Sufficient disk space
# Ensure IP forwarding is enabled
sysctl net.ipv4.ip_forward  # Should be 1
kubeadm init \
  --apiserver-advertise-address=192.168.235.128 \
  --image-repository registry.aliyuncs.com/google_containers \
  --kubernetes-version v1.33.7 \
  --service-cidr=10.96.0.0/12 \
  --pod-network-cidr=10.244.0.0/16 \
  --ignore-preflight-errors=all \
  --cri-socket=unix:///run/containerd/containerd.sock \
  --v=5
Error from server (Forbidden): pods is forbidden: User “system:root” cannot list resource “pods” in API group “” at the cluster scope
alias | grep kubectl
alias kubectl=‘kubectl --kubeconfig=/etc/kubernetes/admin.conf --insecure-skip-tls-verify=true --as=system:root’
权限问题根源:kubectl 被设置了全局别名 --as=system:root
unalias kubectl

alias | grep kubectl

kubectl get nodes
kube-system coredns-757cc6c8f8-7sbd9 0/1 ContainerCreating 0 21m
Failed to create pod sandbox: rpc error: code = Unknown desc = failed to setup network for sandbox
问题原因:Kubernetes CNI插件loopback缺失
步骤1:下载并安装CNI插件
# 下载CNI插件(根据架构选择)
CNI_VERSION="v1.3.0"
ARCH="amd64"  # 或 arm64

mkdir -p /opt/cni/bin

curl -L "https://github.com/containernetworking/plugins/releases/download/${CNI_VERSION}/cni-plugins-linux-${ARCH}-${CNI_VERSION}.tgz" | \
  sudo tar -C /opt/cni/bin -xz
步骤2:验证插件已安装
ls -lh /opt/cni/bin/
步骤3:重启相关服务
这里换成自己的pod
# 重启kubelet
sudo systemctl restart kubelet

# 删除失败的Pod让它们重建
kubectl delete pod coredns-757cc6c8f8-7sbd9 -n kube-system
kubectl delete pod coredns-757cc6c8f8-k5bv8 -n kube-system
步骤4:检查状态
# 等待30秒后检查
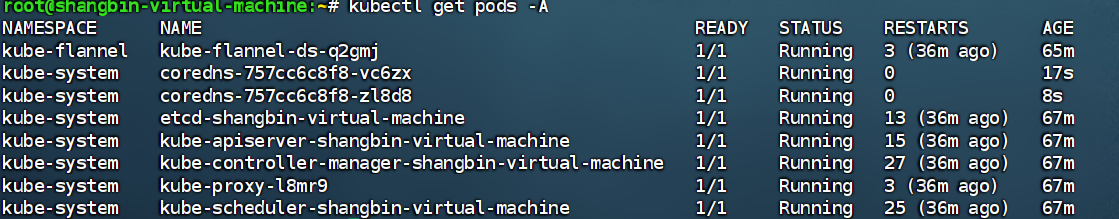
kubectl get pods -A

# 查看详细事件
kubectl describe pod -n kube-system coredns-757cc6c8f8-xxxxx
Warning FailedScheduling 2m46s default-scheduler 0/1 nodes are available: 1 node(s) had untolerated taint {node-role.kubernetes.io/control-plane: }. preemption: 0/1 nodes are available: 1 Preemption is not helpful for scheduling.
Pending 唯一原因:污点容忍未生效
# 命令1:删除 control-plane 污点 (你的日志报错的就是这个,重中之重)
kubectl taint nodes --all node-role.kubernetes.io/control-plane:NoSchedule-
# 命令2:删除 master 污点 (兼容旧版本,双重保险)
kubectl taint nodes --all node-role.kubernetes.io/master:NoSchedule-
执行结果提示 taint not found 也没关系,证明污点已经被彻底删除,就是成功!
failed to create snapshot: missing parent “k8s.io/64/sha256:d8bdedd33a4e22f5cb6ca641a7ada5f9e6a92ad001589480818a136184c7ce34” bucket: not found
A control plane component may have crashed or exited when started by the container runtime.
To troubleshoot, list all containers using your preferred container runtimes CLI.
Here is one example how you may list all running Kubernetes containers by using crictl:
        - 'crictl --runtime-endpoint unix:///run/containerd/containerd.sock ps -a | grep kube | grep -v pause'
        Once you have found the failing container, you can inspect its logs with:
        - 'crictl --runtime-endpoint unix:///run/containerd/containerd.sock logs CONTAINERID'

[kube-scheduler check failed at https://127.0.0.1:10259/livez: Get "https://127.0.0.1:10259/livez": dial tcp 127.0.0.1:10259: connect: connection refused, kube-apiserver check failed at https://192.168.235.128:6443/livez: Get "https://192.168.235.128:6443/livez?timeout=10s": dial tcp 192.168.235.128:6443: connect: connection refused, kube-controller-manager check failed at https://127.0.0.1:10257/healthz: Get "https://127.0.0.1:10257/healthz": dial tcp 127.0.0.1:10257: connect: connection refused]
failed while waiting for the control plane to start
k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/init.runWaitControlPlanePhase
        k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/init/waitcontrolplane.go:105
k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/workflow.(*Runner).Run.func1
        k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/workflow/runner.go:261
k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/workflow.(*Runner).visitAll
        k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/workflow/runner.go:450
k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/workflow.(*Runner).Run
        k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/workflow/runner.go:234
k8s.io/kubernetes/cmd/kubeadm/app/cmd.newCmdInit.func1
        k8s.io/kubernetes/cmd/kubeadm/app/cmd/init.go:134
github.com/spf13/cobra.(*Command).execute
        github.com/spf13/cobra@v1.8.1/command.go:985
github.com/spf13/cobra.(*Command).ExecuteC
        github.com/spf13/cobra@v1.8.1/command.go:1117
github.com/spf13/cobra.(*Command).Execute
        github.com/spf13/cobra@v1.8.1/command.go:1041
k8s.io/kubernetes/cmd/kubeadm/app.Run
        k8s.io/kubernetes/cmd/kubeadm/app/kubeadm.go:47
main.main
        k8s.io/kubernetes/cmd/kubeadm/kubeadm.go:25
runtime.main
        runtime/proc.go:283
runtime.goexit
        runtime/asm_amd64.s:1700
error execution phase wait-control-plane
k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/workflow.(*Runner).Run.func1
        k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/workflow/runner.go:262
k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/workflow.(*Runner).visitAll
        k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/workflow/runner.go:450
k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/workflow.(*Runner).Run
        k8s.io/kubernetes/cmd/kubeadm/app/cmd/phases/workflow/runner.go:234
k8s.io/kubernetes/cmd/kubeadm/app/cmd.newCmdInit.func1
        k8s.io/kubernetes/cmd/kubeadm/app/cmd/init.go:134
github.com/spf13/cobra.(*Command).execute
        github.com/spf13/cobra@v1.8.1/command.go:985
github.com/spf13/cobra.(*Command).ExecuteC
        github.com/spf13/cobra@v1.8.1/command.go:1117
github.com/spf13/cobra.(*Command).Execute
        github.com/spf13/cobra@v1.8.1/command.go:1041
k8s.io/kubernetes/cmd/kubeadm/app.Run
        k8s.io/kubernetes/cmd/kubeadm/app/kubeadm.go:47
main.main
        k8s.io/kubernetes/cmd/kubeadm/kubeadm.go:25
runtime.main
        runtime/proc.go:283
runtime.goexit
        runtime/asm_amd64.s:1700
rm -rf /var/lib/containerd/*
rm -rf /run/containerd/*
API Server 未启动
systemctl start kubelet
kubectl get nodes
kubectl get pods -A
更多推荐

 5
 0
- 0


 已为社区贡献1条内容

所有评论(0)