
二、FlinkCDC-DataStream_状态后端
水善利万物而不争,处众人之所恶,故几于道💦
CDC中有个配置是source的启动模式:
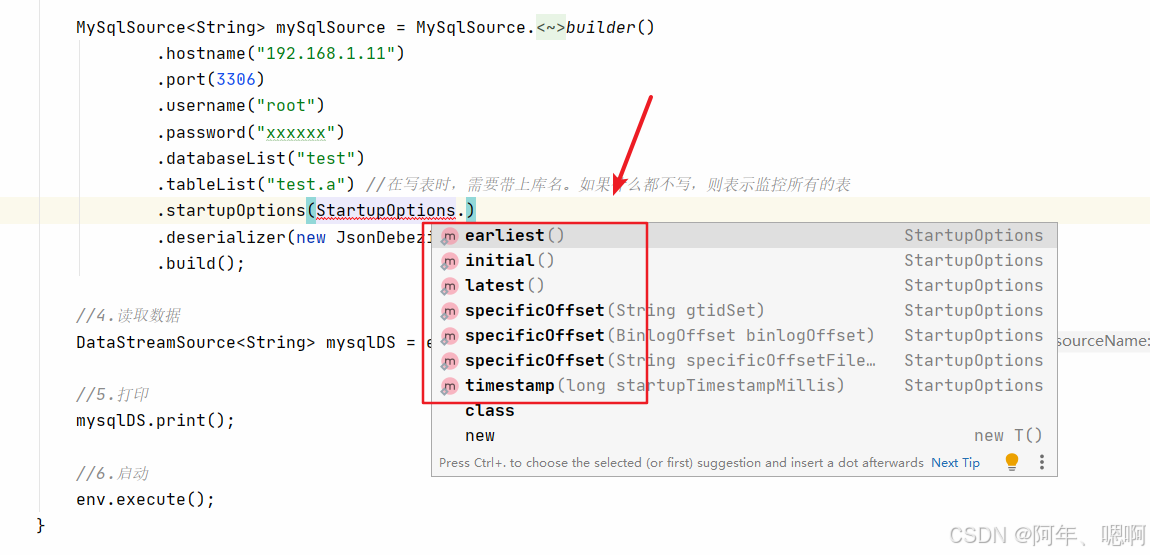
earliest:启动后,从binlog的开头开始读取
initial:首次启动时,对库表执行初始快照,然后继续读取最新的binlog,也就是开始是全量,后续增量
latest:从binlog的末尾读取,只获取最新的
specificOffset:从指定的偏移量读取binlog
timestamp:从指定的时间戳开始读取binlog
这个initial如何理解了,idea里面停掉后,重新启动又会重新从头读取一遍,这个是没有保存状态,所以没有根据上次停掉的时候的状态启动,所以尽管参数设置成这样了,但是没有把状态保存下来,所以就没有首次增量,重新启动后继续从断点处读的效果。想要实现那样的效果要设置checkpoint
文章目录
1. demo演示代码
这个代码的checkpoint,不全,不能在生产上用,仅用于功能演示,下一个方案可以在生产用
import com.ververica.cdc.connectors.mysql.source.MySqlSource;
import com.ververica.cdc.connectors.mysql.table.StartupOptions;
import com.ververica.cdc.debezium.JsonDebeziumDeserializationSchema;
import org.apache.flink.api.common.eventtime.WatermarkStrategy;
import org.apache.flink.streaming.api.CheckpointingMode;
import org.apache.flink.streaming.api.datastream.DataStreamSource;
import org.apache.flink.streaming.api.environment.StreamExecutionEnvironment;

/**
 * Author: Pepsi
 * Date: 2026/2/8
 * Desc:
 */
public class FlinkCDC_DataStream {

    public static void main(String[] args) throws Exception {
        // 1. 获取flink执行环境
        StreamExecutionEnvironment env = StreamExecutionEnvironment.getExecutionEnvironment();
        env.setParallelism(1);
        // 2. 开启CheckPoint
        // 2.1 每5s执行一次checkpoint
        env.enableCheckpointing(5000L);
        // 2.2 执行checkpoint的超时时间,10s,如果10s还没执行完这个checkpoint就认为这次checkpoint失败了
        env.getCheckpointConfig().setCheckpointTimeout(10000L);
        // 2.3 checkpoint的存储路径
        env.getCheckpointConfig().setCheckpointStorage("hdfs://hadoop101:8020/FlinkCDC/ck");
        // 2.4 checkpoint的模式,精准一次,这个要想生效要保证source和sink支持,source支持重放,kafka
        env.getCheckpointConfig().setCheckpointingMode(CheckpointingMode.EXACTLY_ONCE);
        // 2.5 最大同时存在多少个checkpoint
        env.getCheckpointConfig().setMaxConcurrentCheckpoints(1);


		// 3. 使用FlinkCDC构建MysqlSource
        MySqlSource<String> mySqlSource = MySqlSource.<String>builder()
                .hostname("192.168.1.11")
                .port(3306)
                .username("root")
                .password("xxxxxx")
                .databaseList("test")
                .tableList("test.a") //在写表时,需要带上库名。如果什么都不写,则表示监控所有的表
                .startupOptions(StartupOptions.initial())
                .deserializer(new JsonDebeziumDeserializationSchema()) // 返回String
                .build();

        //4.读取数据
        DataStreamSource<String> mysqlDS = env.fromSource(mySqlSource, WatermarkStrategy.noWatermarks(), "mysql-source");

        //5.打印
        mysqlDS.print();

        //6.启动
        env.execute();
    }
}
2. 打包上传服务器
用yarn-session模式就行了,把这个jar包提交到yarn上执行,然后在flink任务界面看stdout就行了
① 先启动hadoop集群: hdfs 、yarn都启动
② 然后启动Flink集群:start-cluster.sh
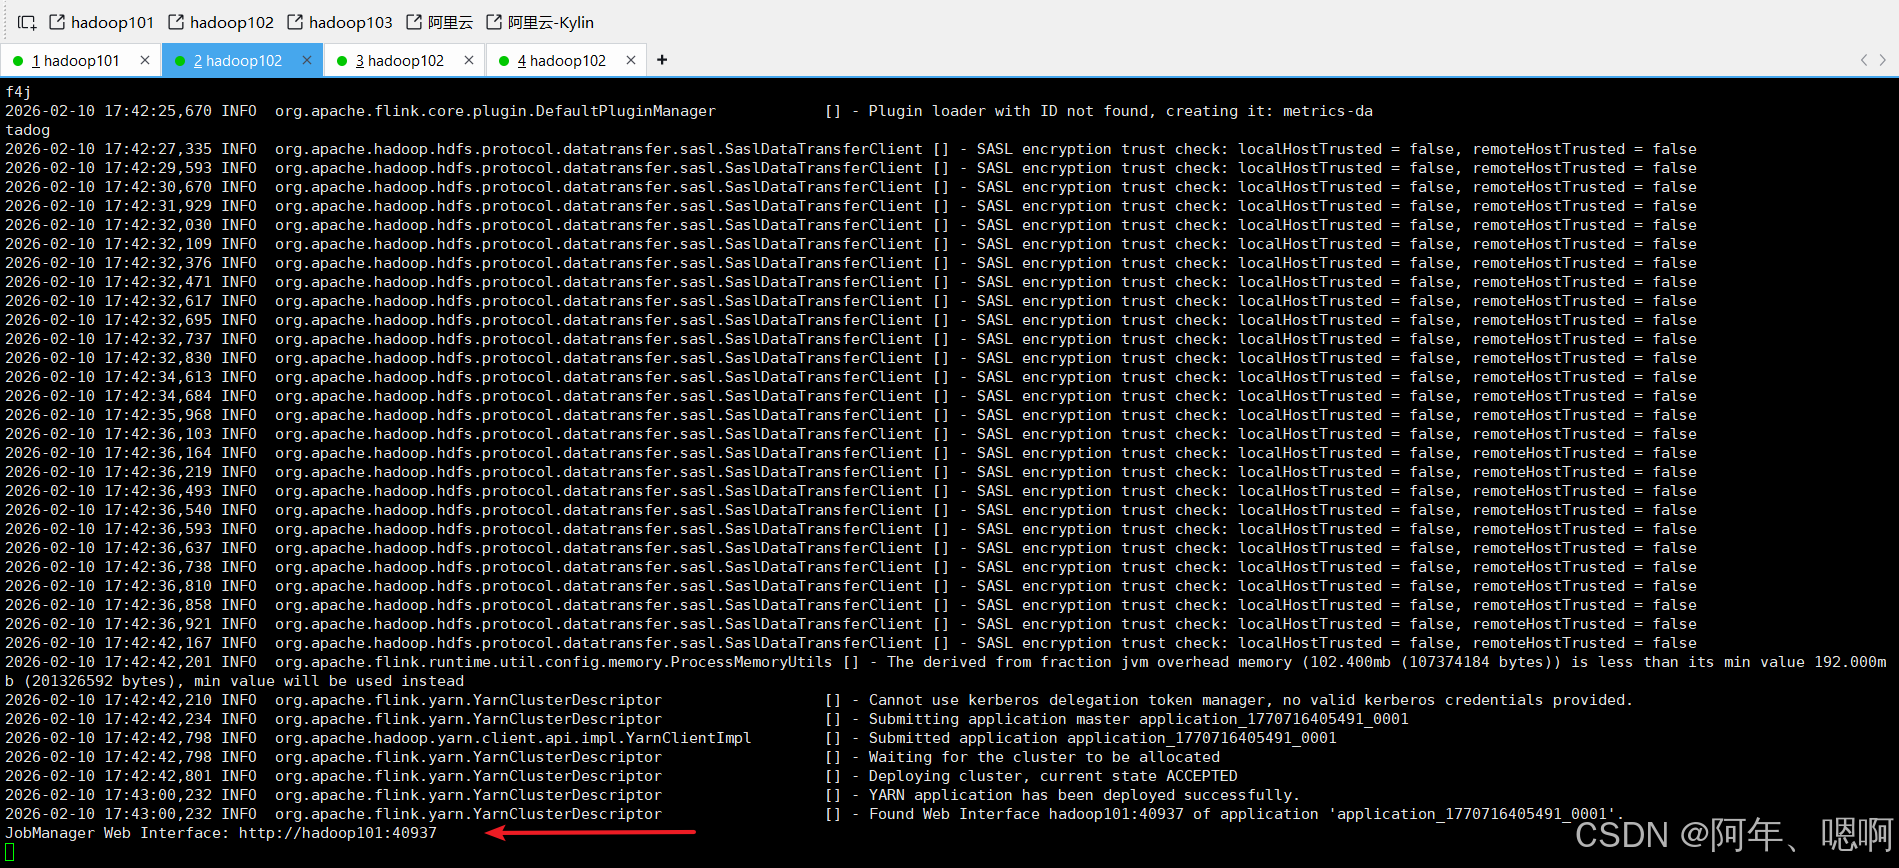
③ 启动一个yarn的session:bin/yarn-session.sh -nm test
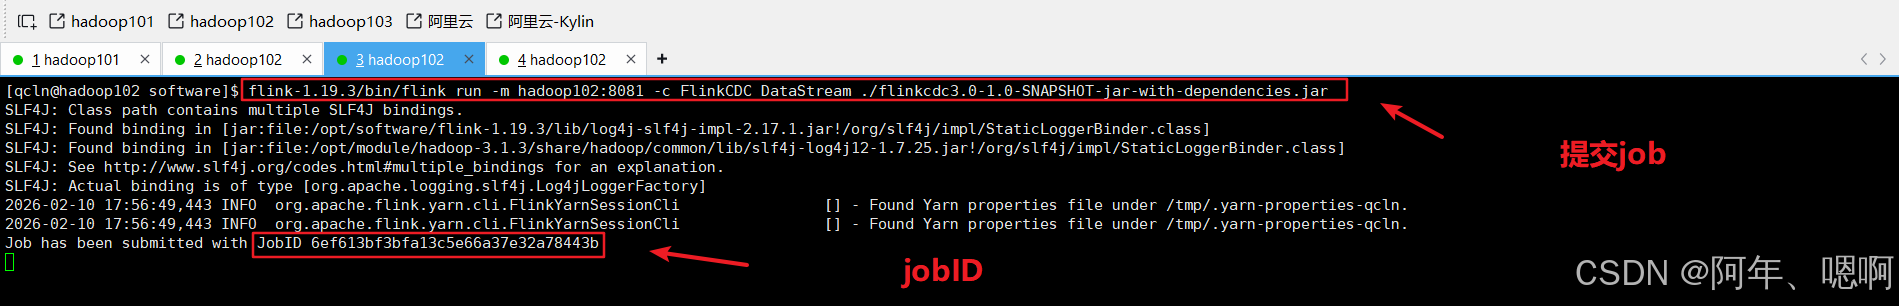
④ 然后在另一个会话窗口提交jar包执行就行
bin/flink run -m hadoop101:8081 -c FlinkCDC_DataStream ./you_jar_name.jar
⑤ 然后在Flink的taskManager页面看stdout输出日志
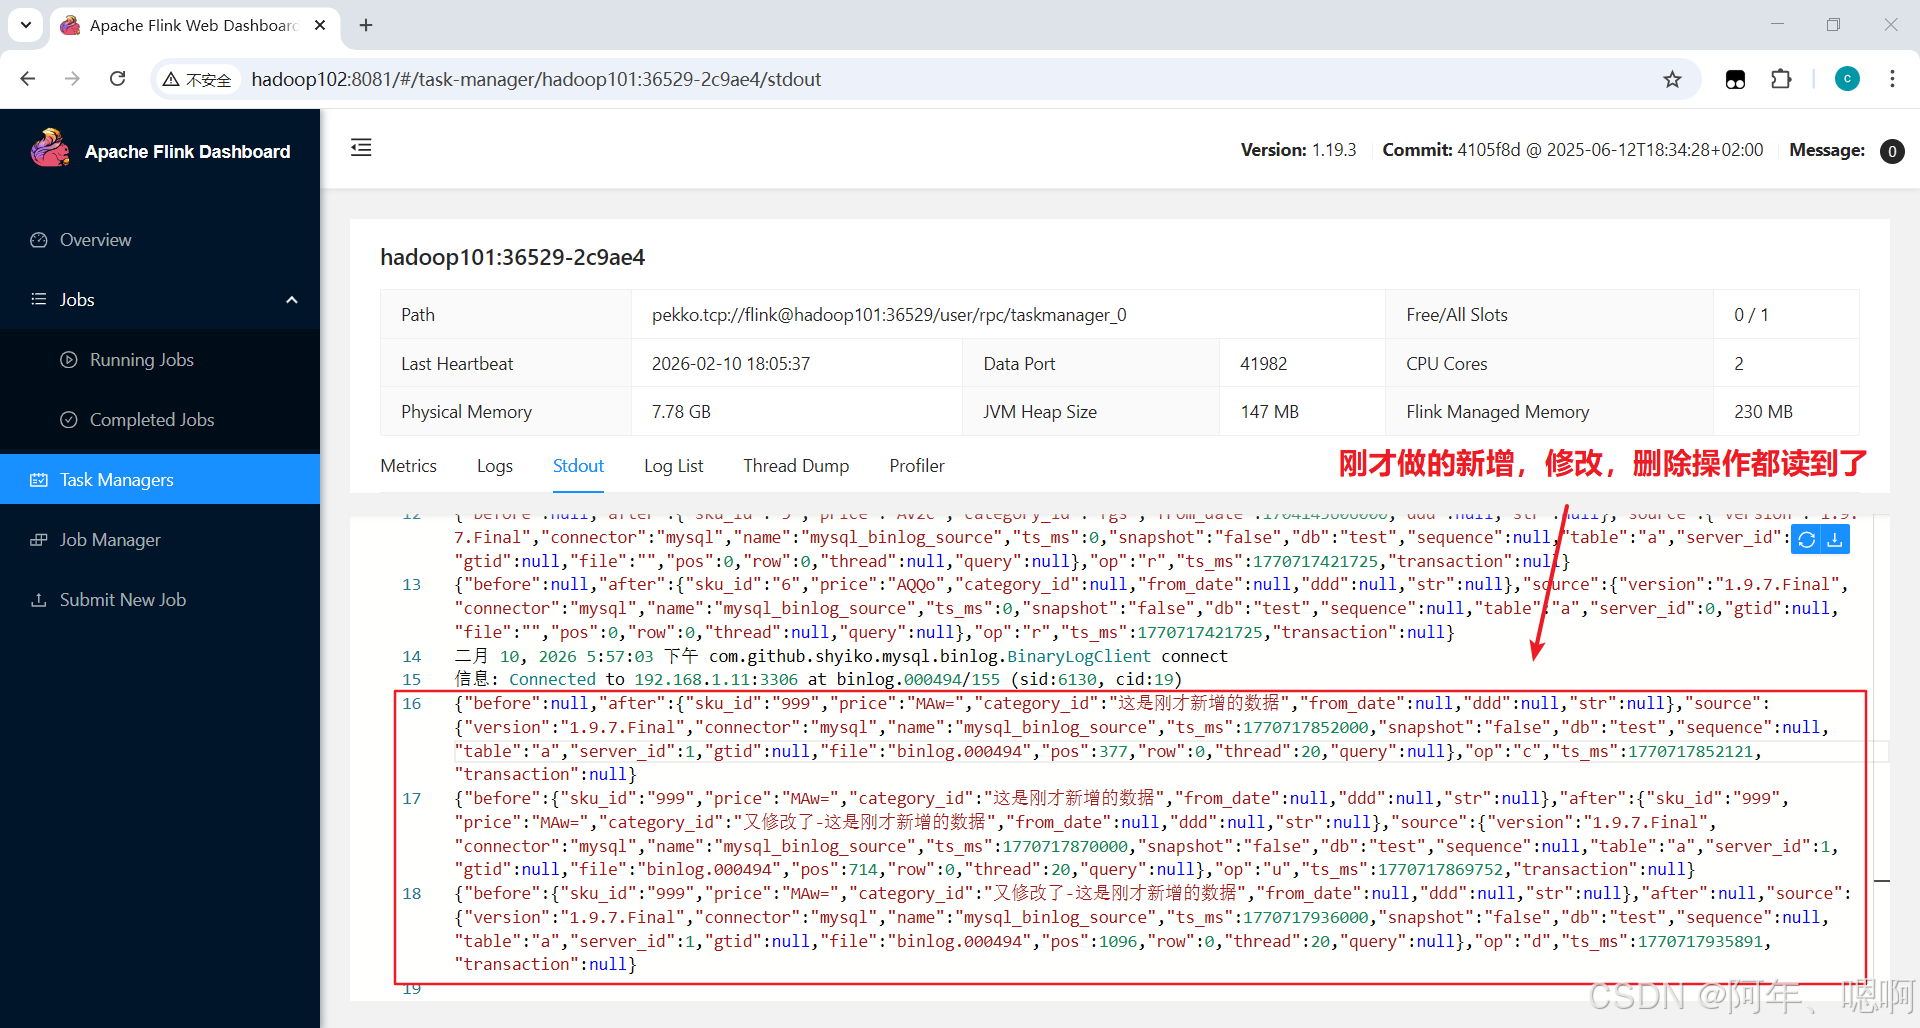
⑥ 在MySQL里面对表数据进行增删改操作,查看日志是否抓取到相关binlog
⑦ 手动保存一次checkpoint,然后把应用挂掉,再对MySQL表数据进行增删改操作,然后从指定的savepoint处重启应用,看是否从检查点处重启并消费到程序挂掉后的MySQL操作
手动创建savepoint:bin/flink savepoint JobId hdfs://hadoop102:8020/flinkCDC/save
上面这个JobId要从自己的应用启动后,页面里面有,自己去找。
从指定的savepoint启动:bin/flink run -s hdfs://hadoop102:8020/flinkCDC/save/savepoint-5dadae-02c69ee54885 -c FlinkCDC_DataStream ./you_jar_name.jar
这个savepoint的目录savepoint-5dadae-02c69ee54885也要自己去hdfs目录里面找,或者手动保存后,最后一行日志那里有。
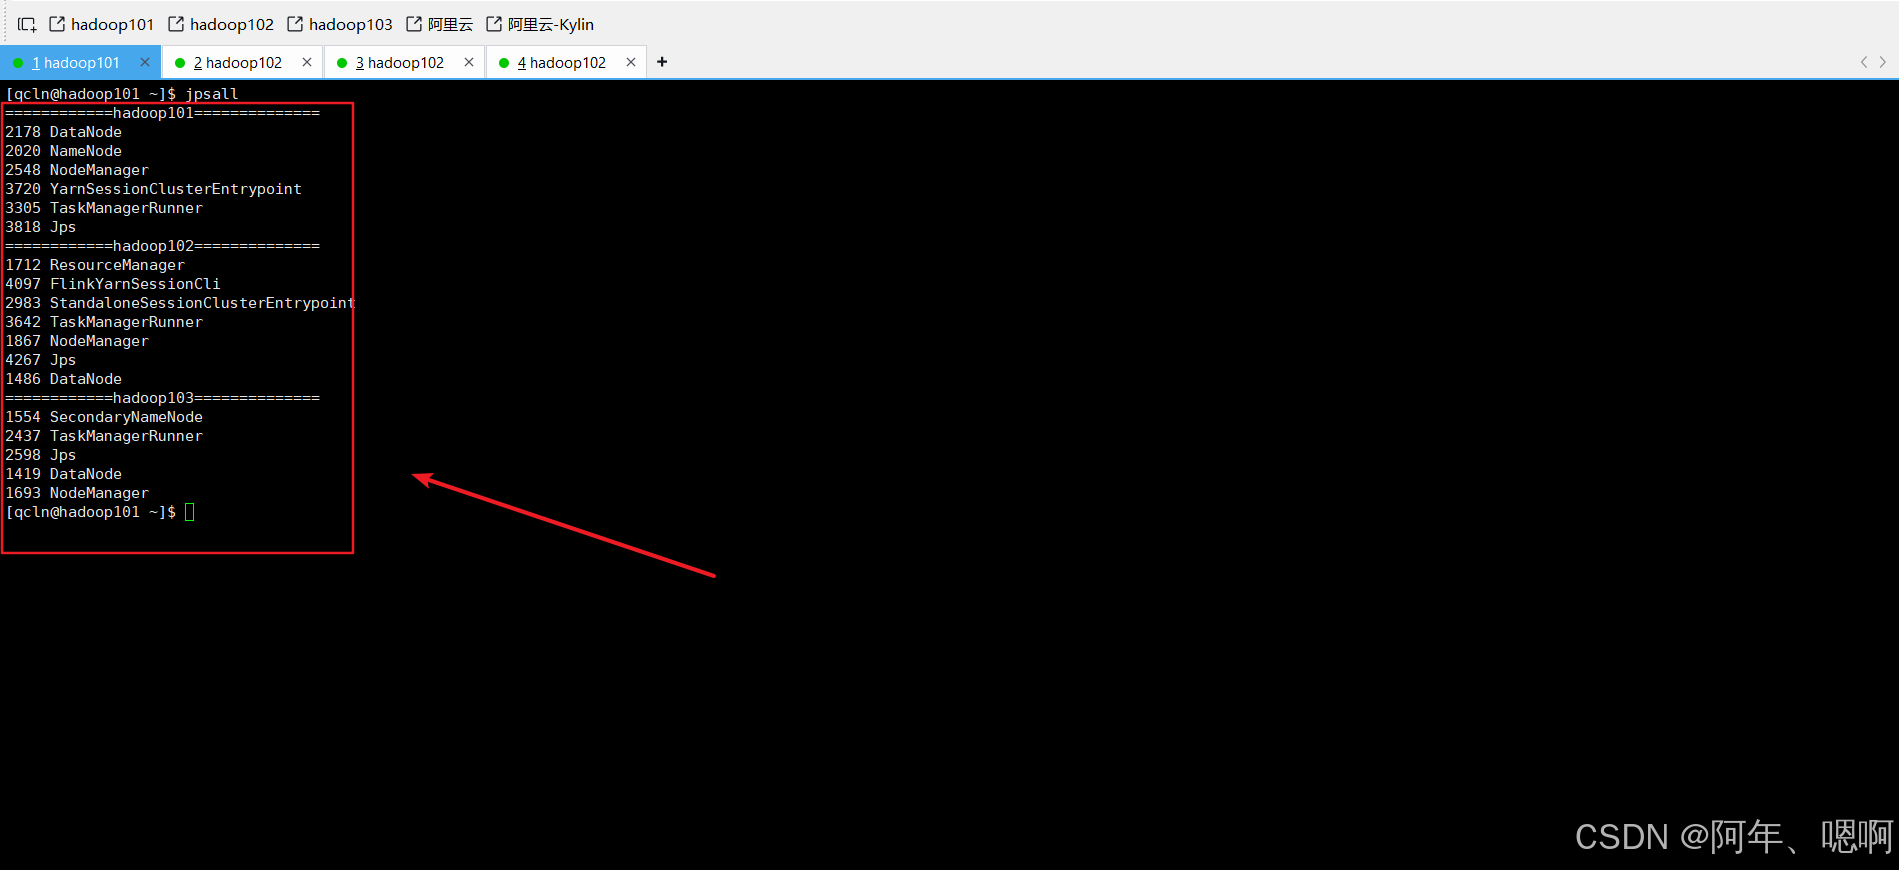
3. Hadoop和Flink集群启动
这些进程
4. 启动yarn-session
5. 提交Job
6. 查看Task Manager的控制台输出日志
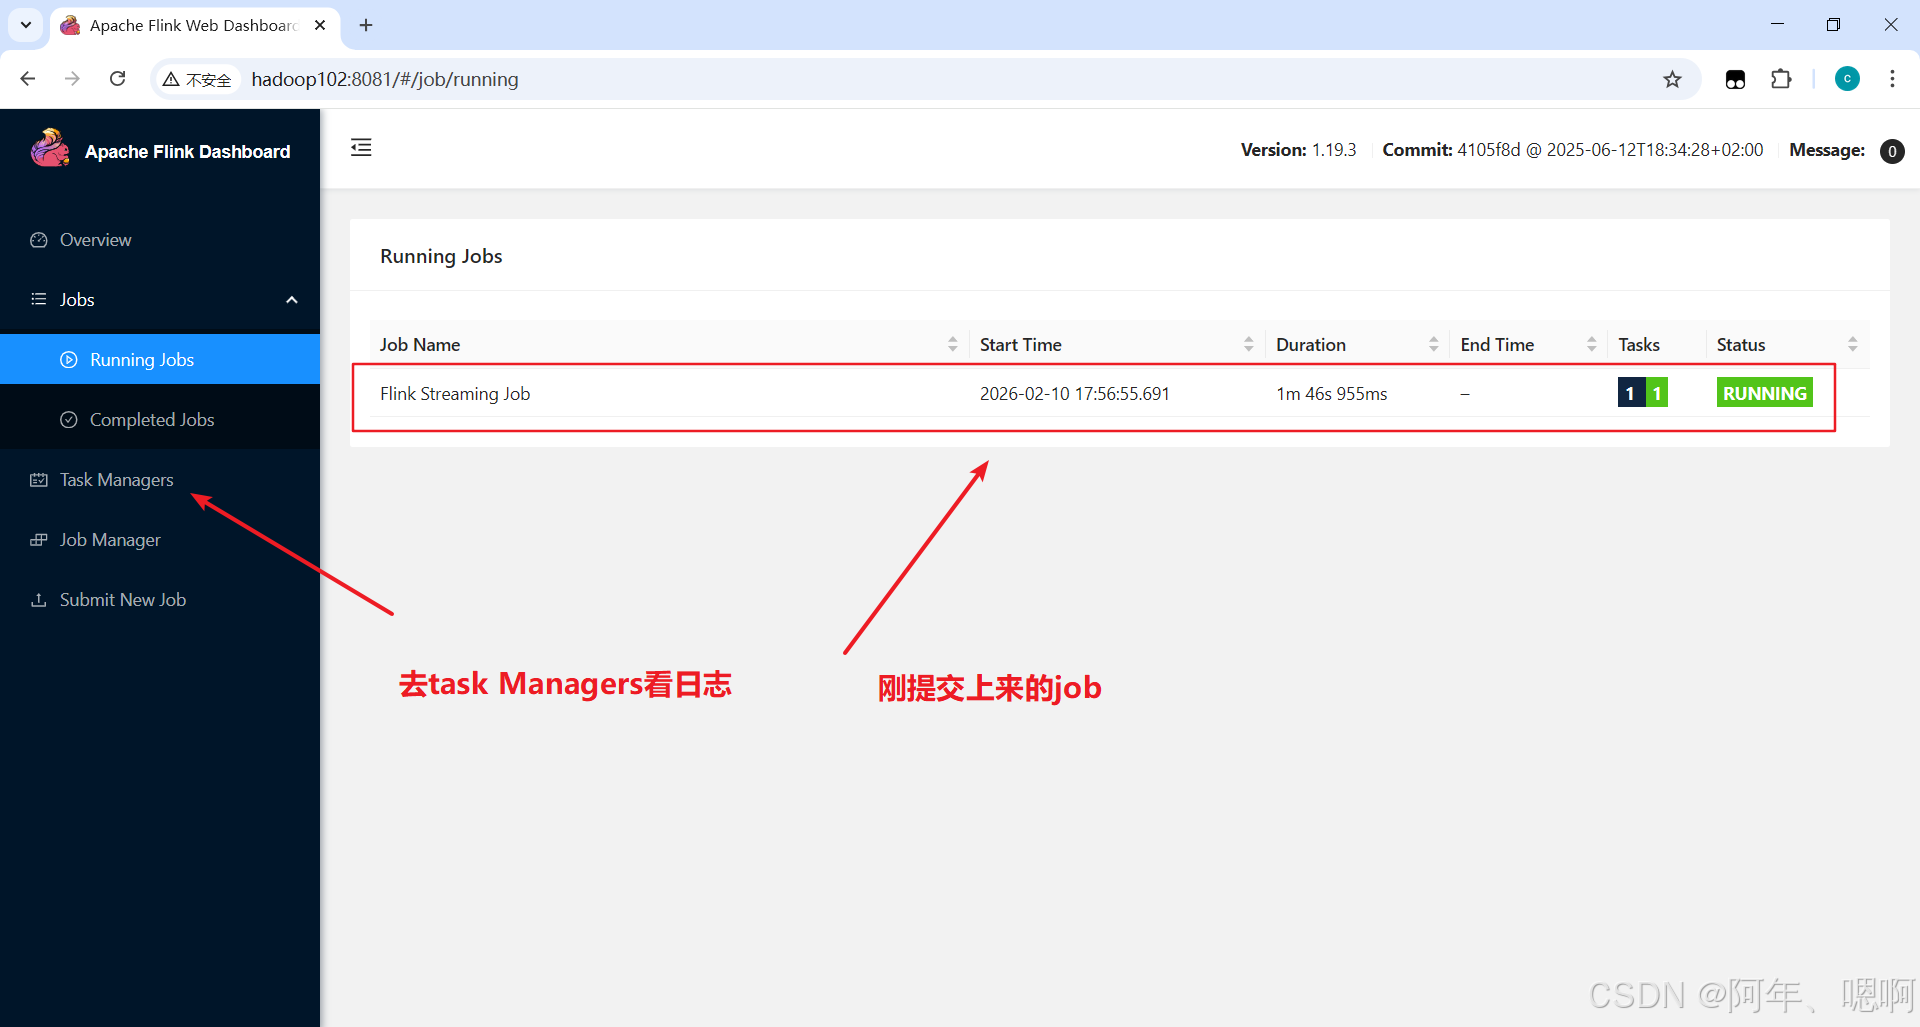
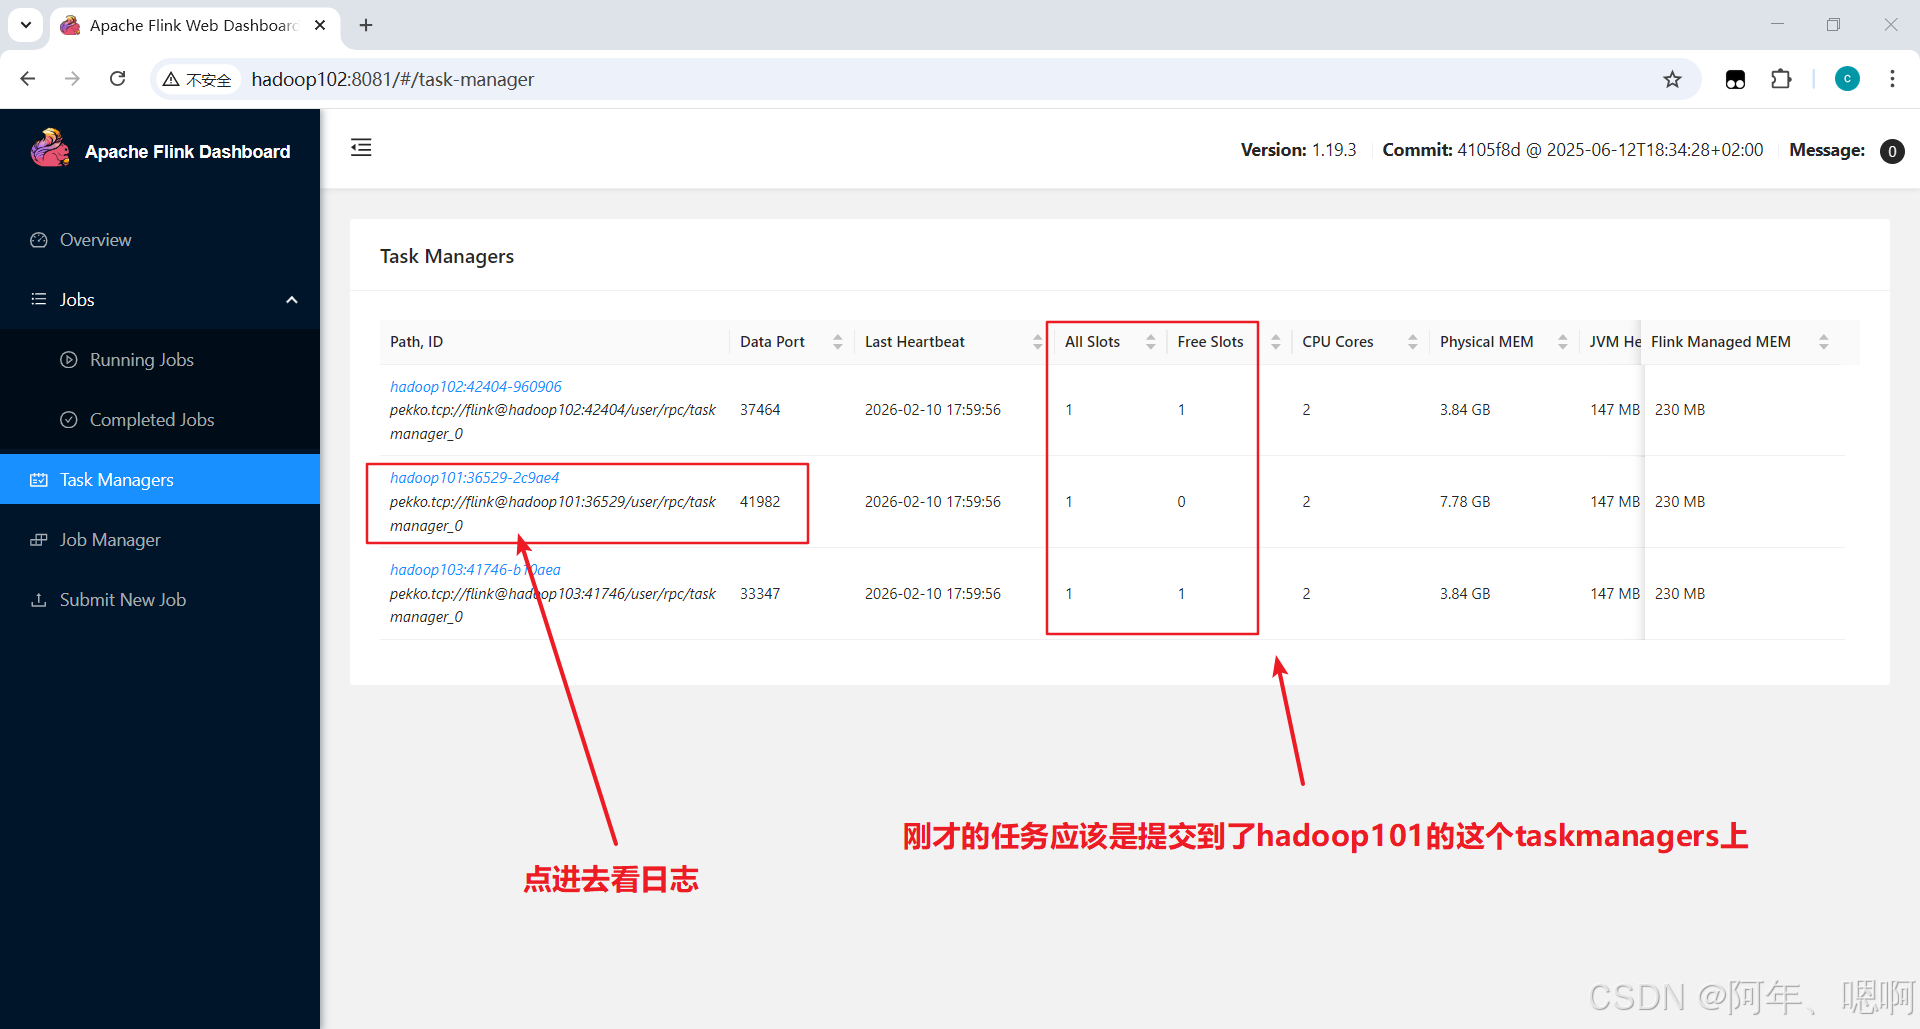
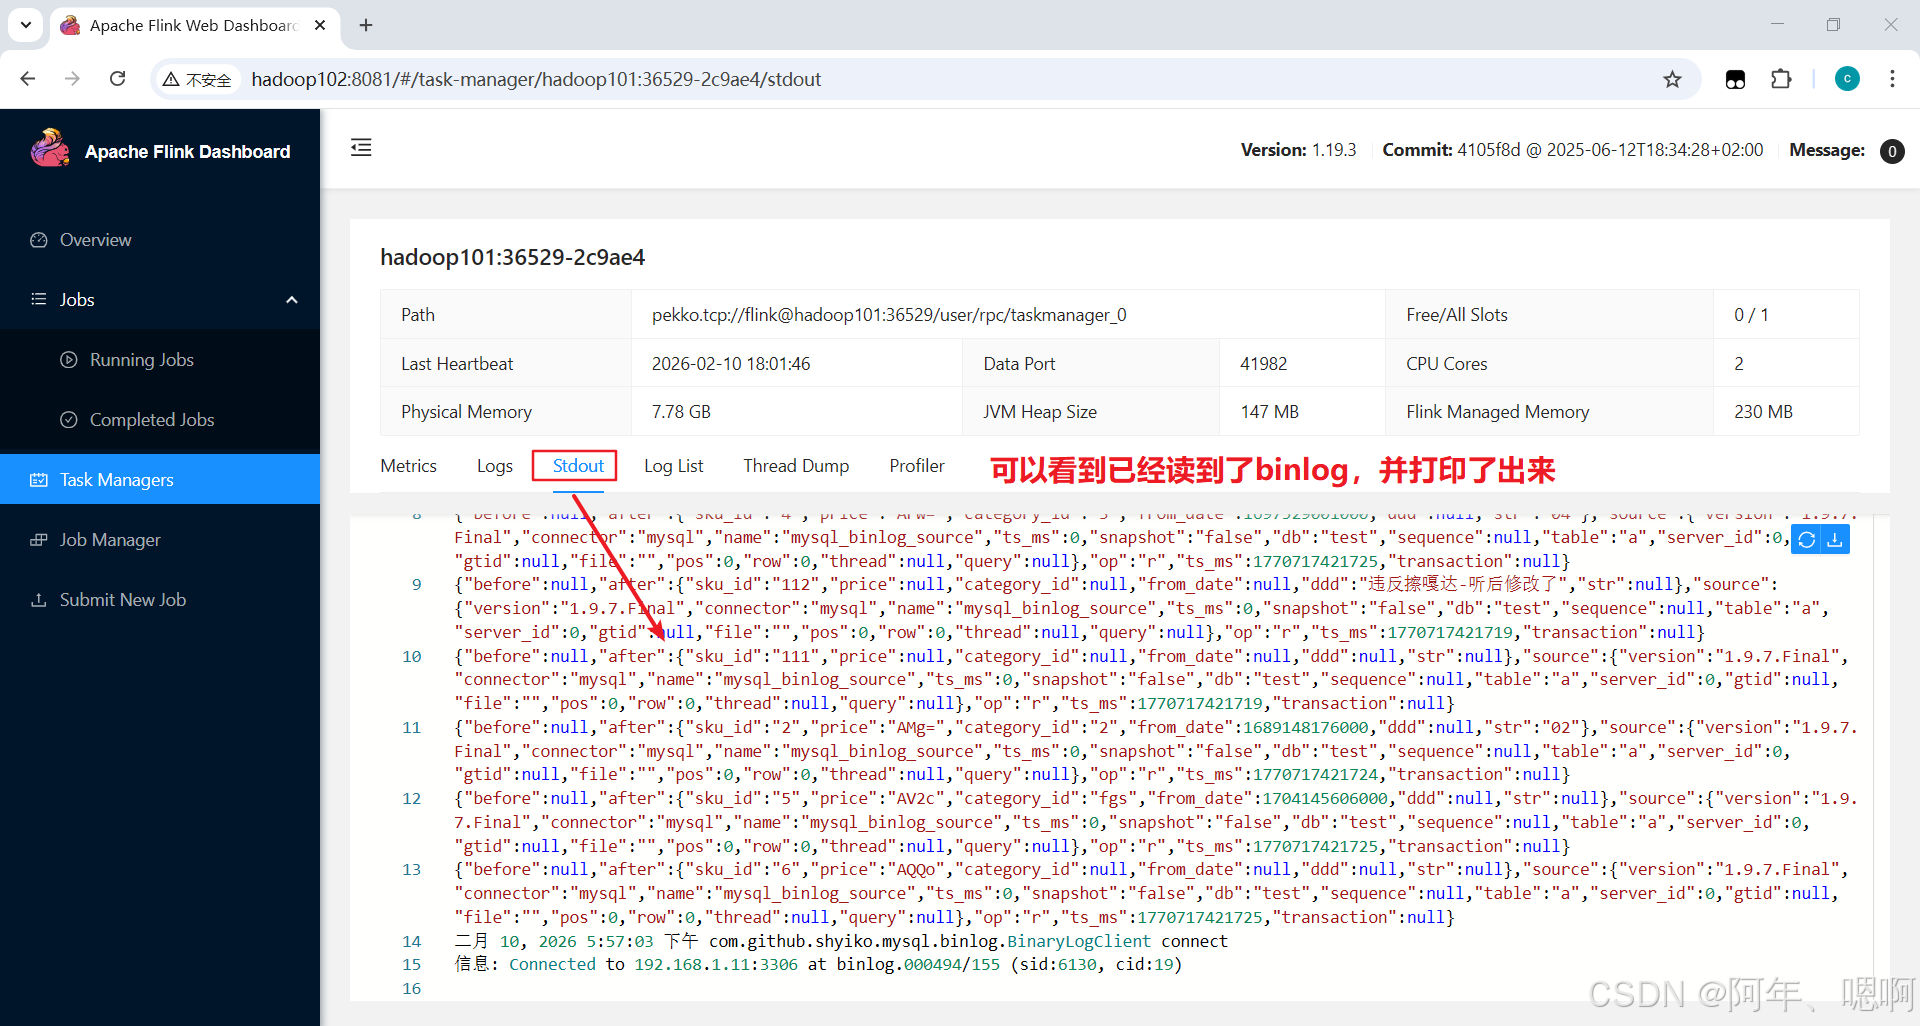
7. MySQL执行增删改操作
对监控的MySQL执行增删改操作后,查看控制台输出
8. 手动保存checkpoint
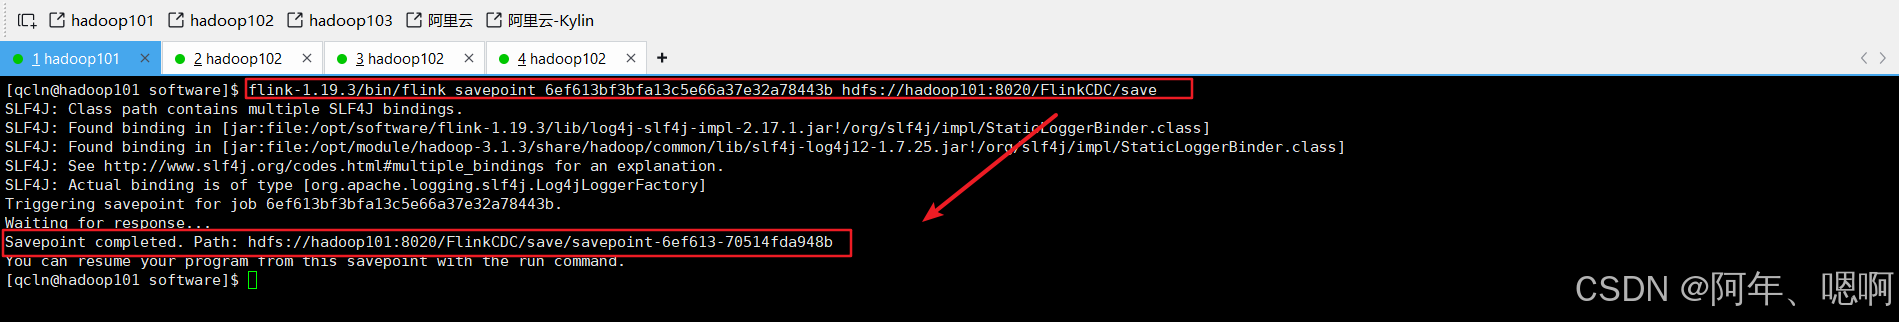
9. 取消刚才的Job
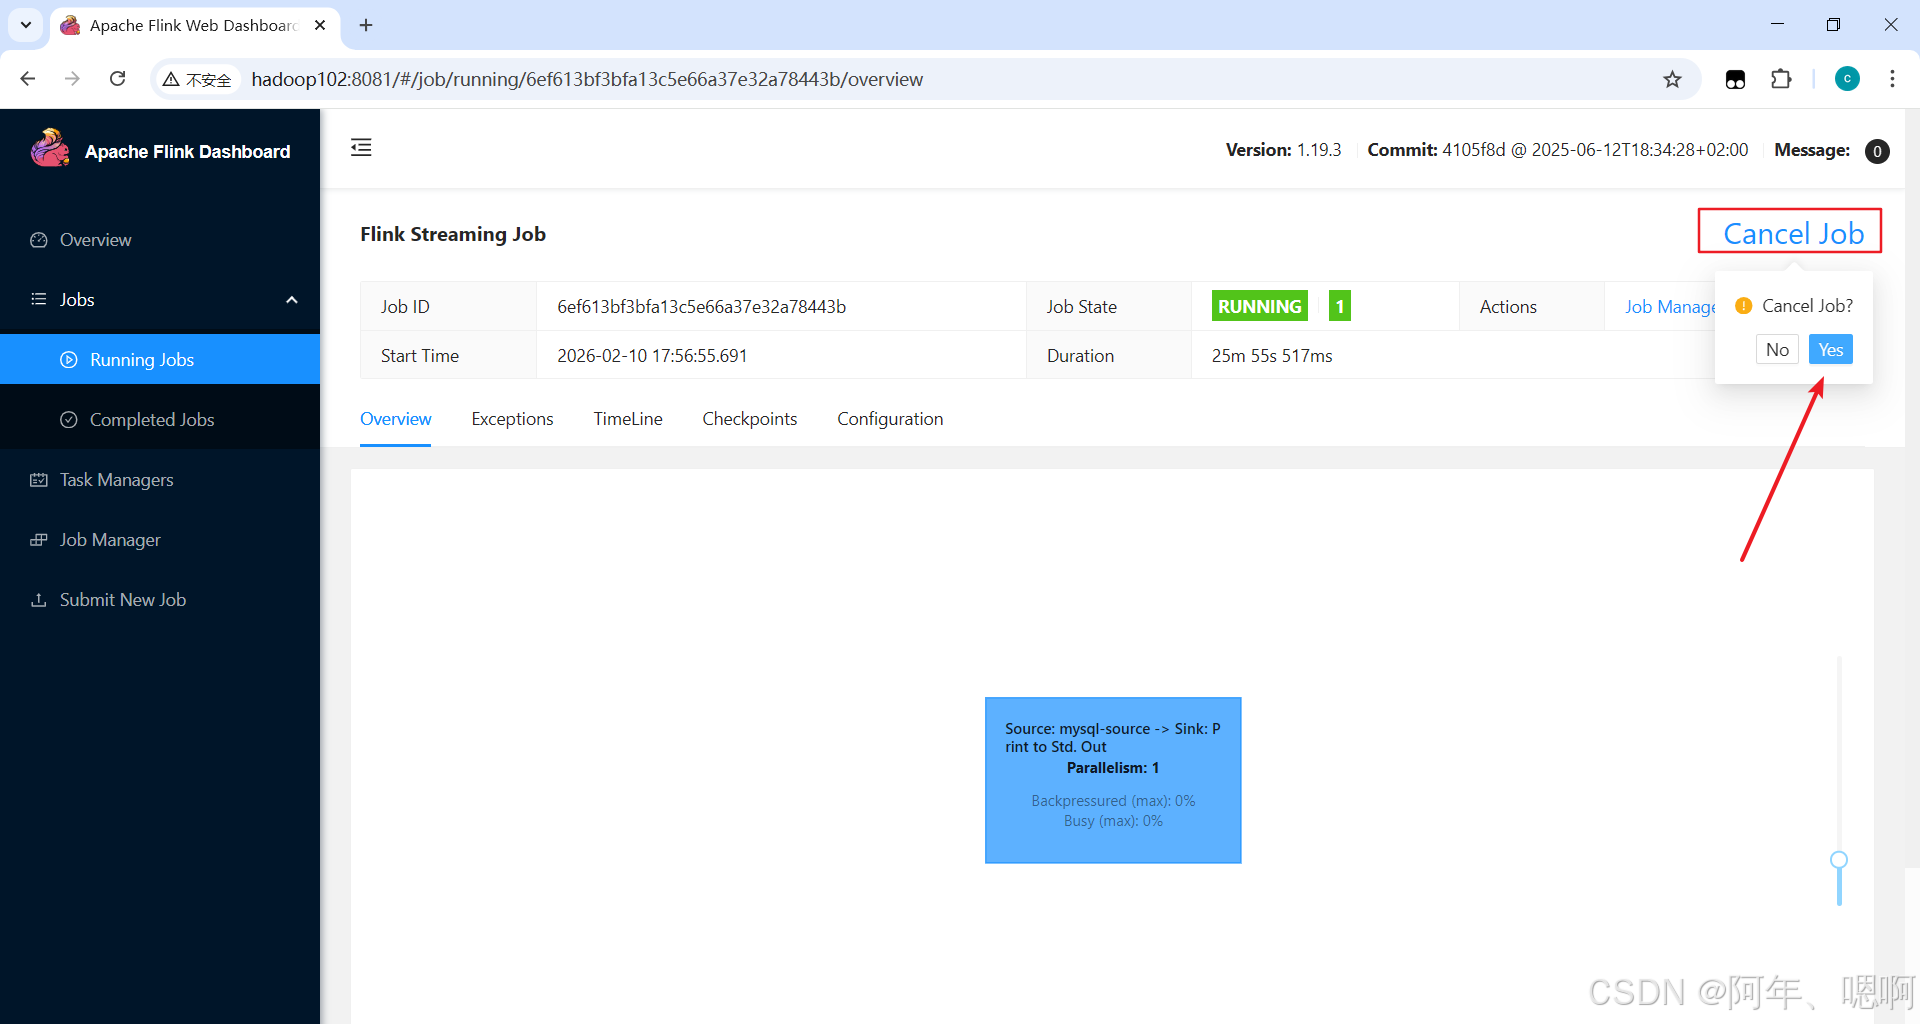
10. Job停止后,对MySQL表执行增删改
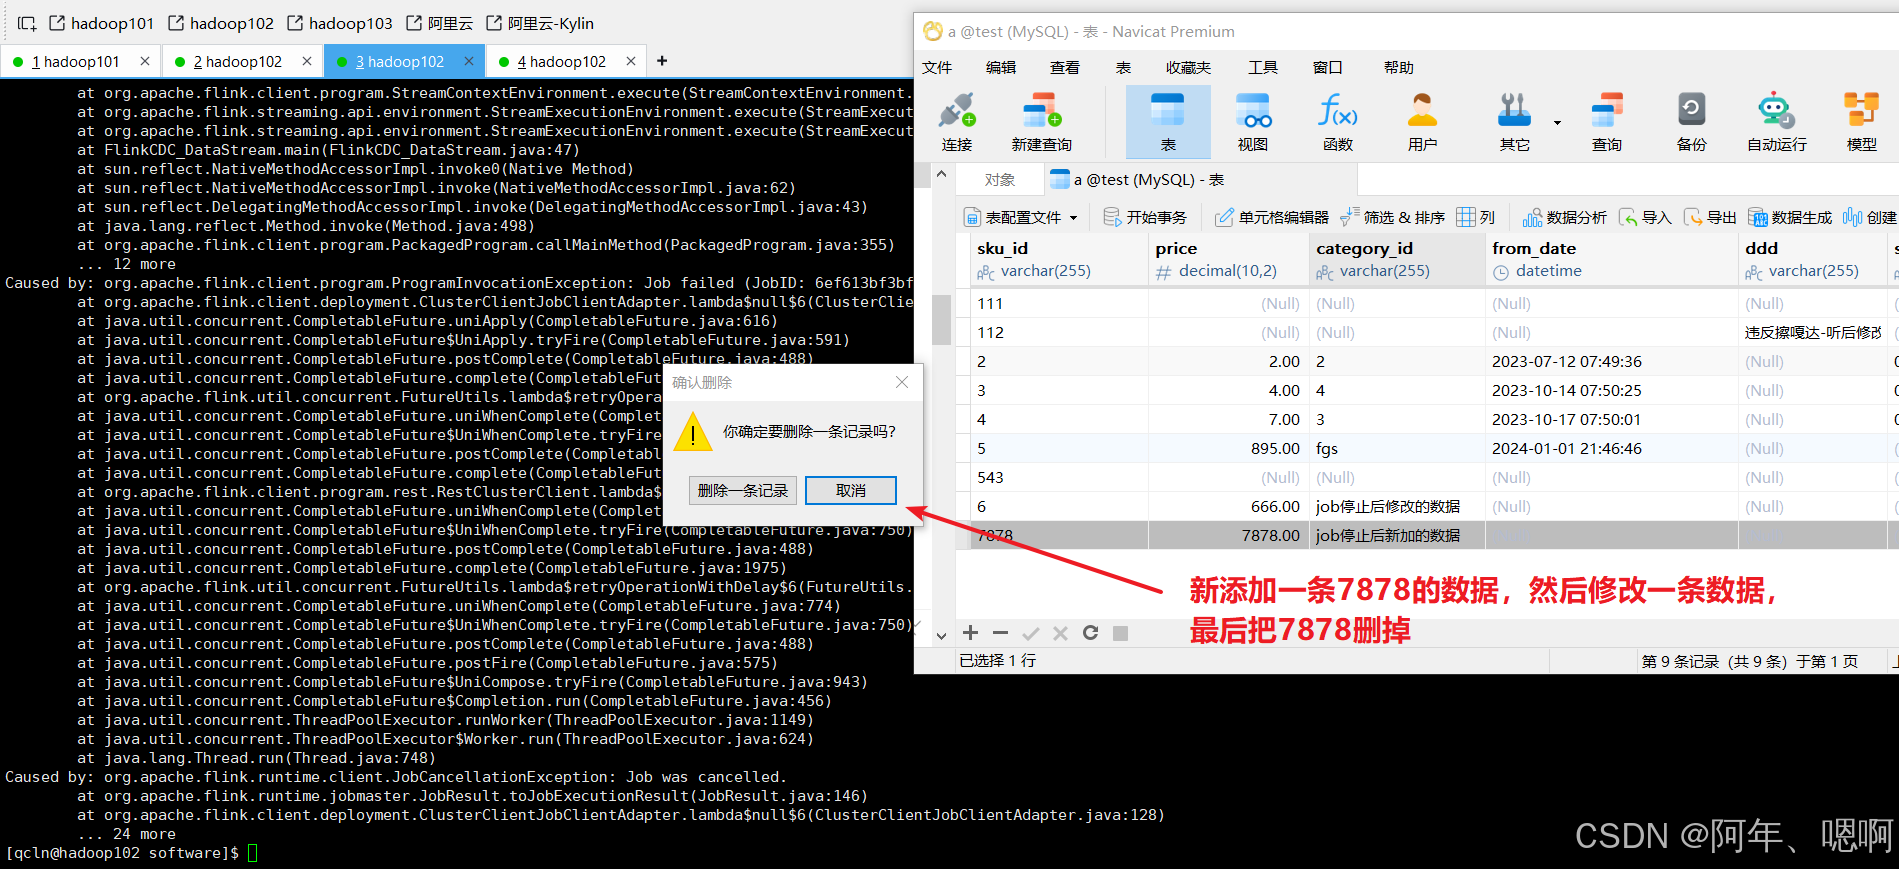
11. 从刚才手动保存的checkpoint点处启动
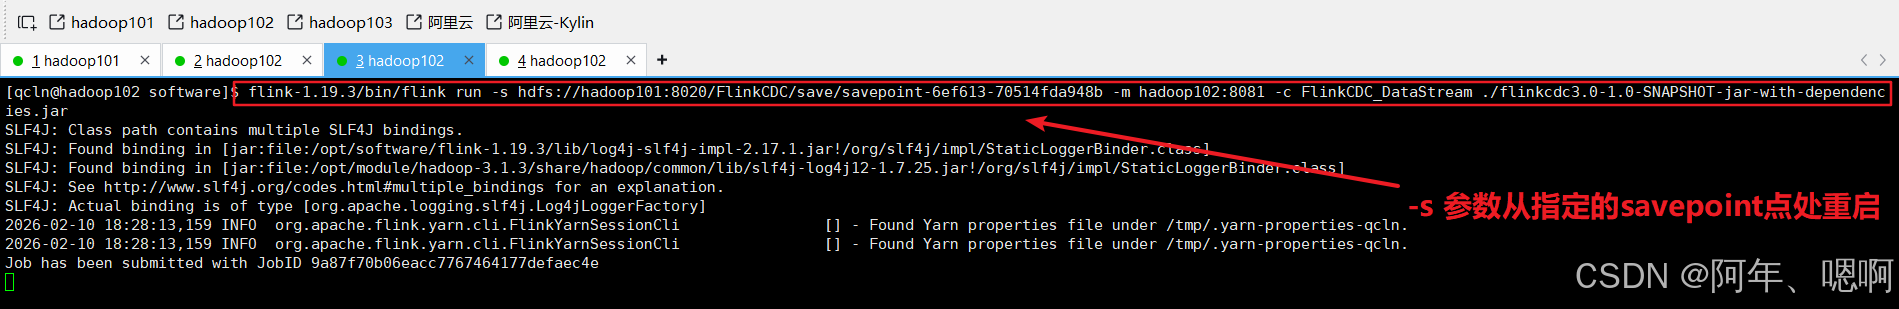
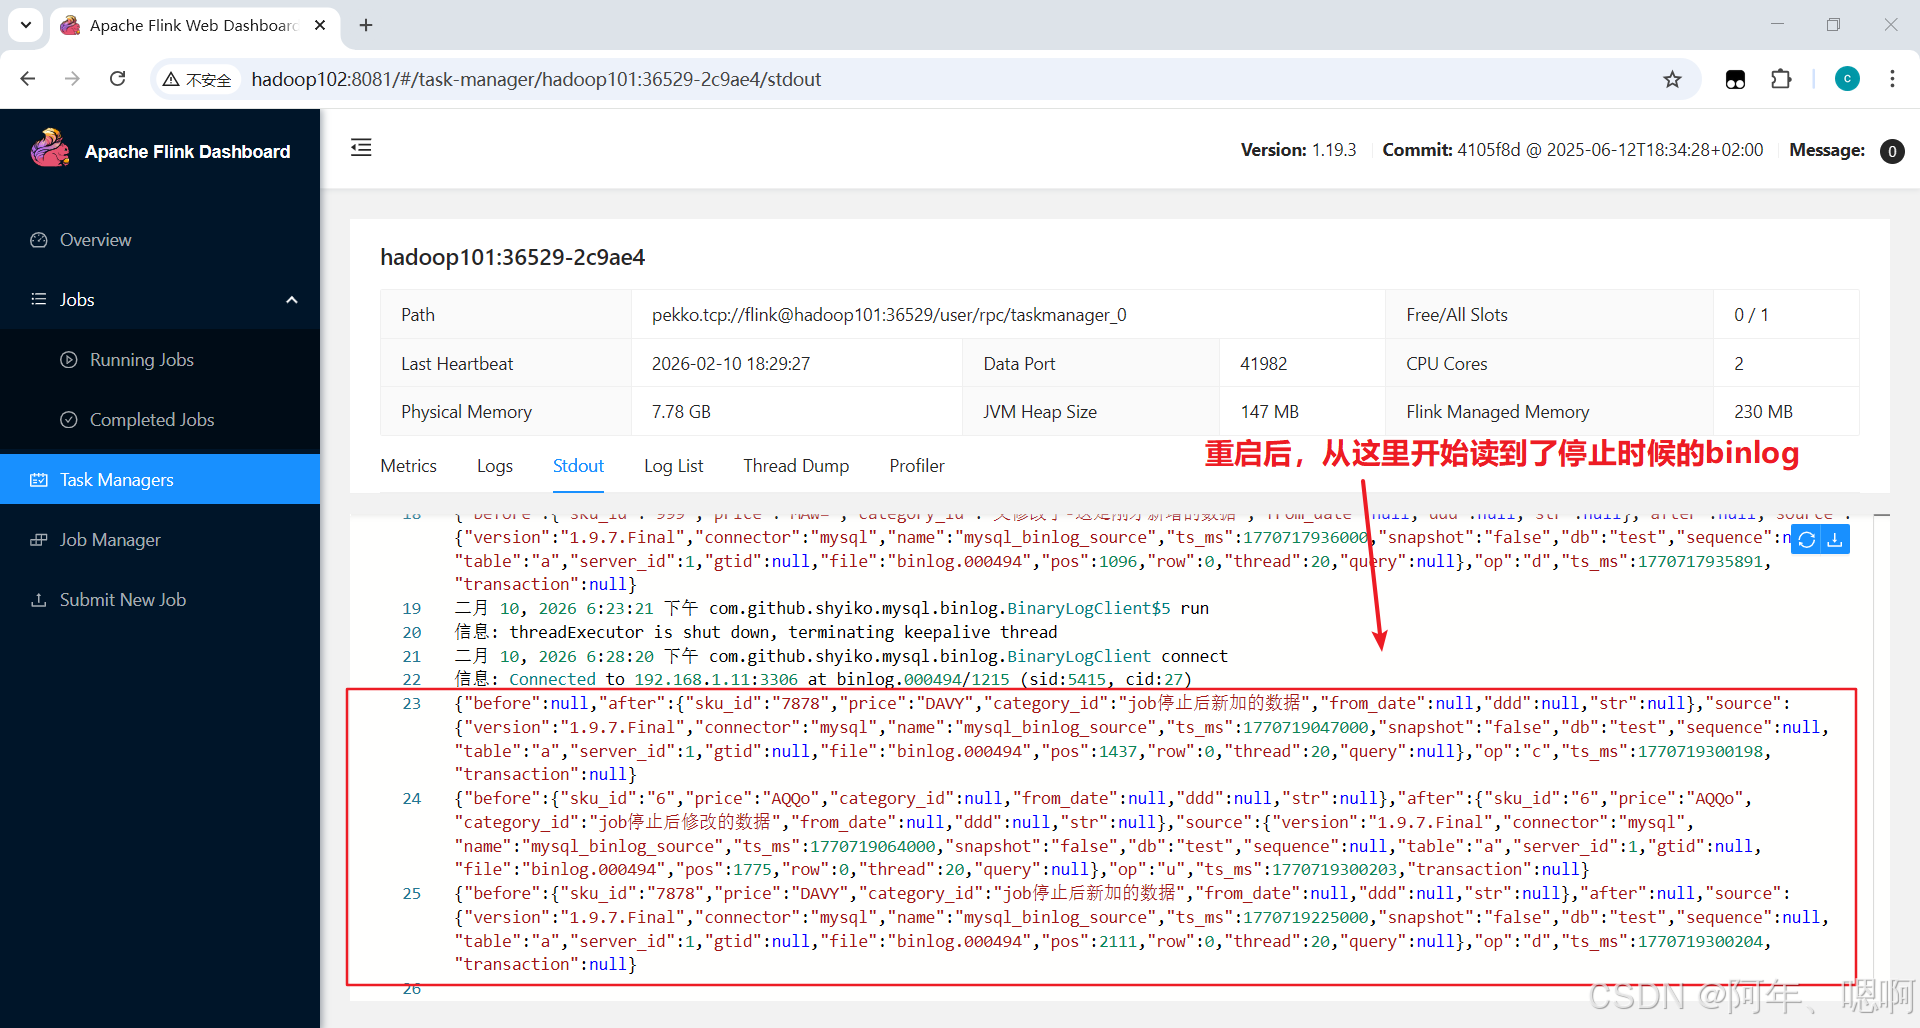
12. 观察重启后Job的控制台
可以看到已经读取到了刚才job停止后MySQL的binlog
相关报错
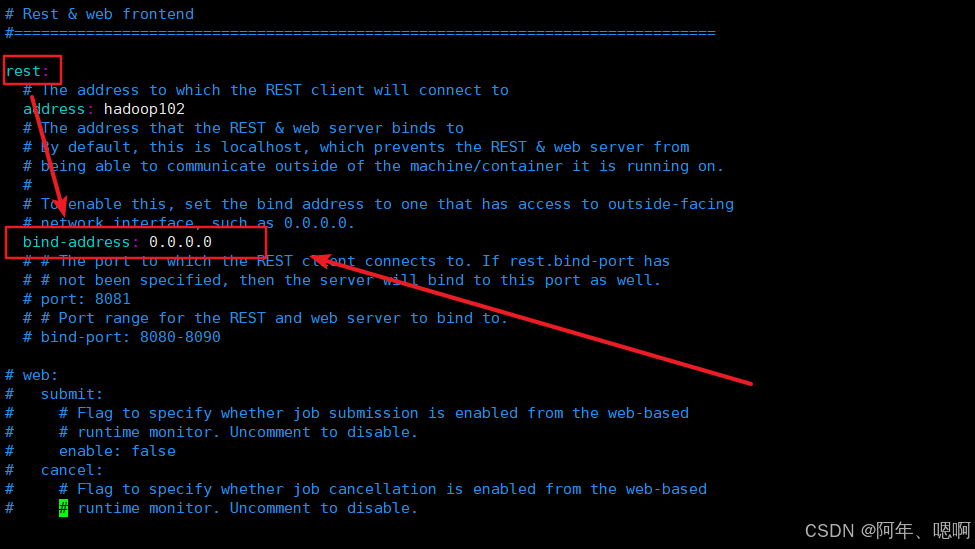
1. Flink集群访问8081拒绝访问
把reset的bind-address地址改成0.0.0.0,每个节点都改下
2. Multiple factories for identifier ‘default’ that implement ‘org.apache.flink.table.delegation.ExecutorFactory’ found in the classpath.
[qcln@hadoop102 flink-1.19.3]$ bin/flink run -m hadoop102:8081 -c FlinkCDC_SQL /opt/software/flinkcdc3.0-1.0-SNAPSHOT-jar-with-dependencies.jar

------------------------------------------------------------
 The program finished with the following exception:

org.apache.flink.client.program.ProgramInvocationException: The main method caused an error: Could not instantiate the executor. Make sure a planner module is on the classpath
	at org.apache.flink.client.program.PackagedProgram.callMainMethod(PackagedProgram.java:372)
	at org.apache.flink.client.program.PackagedProgram.invokeInteractiveModeForExecution(PackagedProgram.java:222)
	at org.apache.flink.client.ClientUtils.executeProgram(ClientUtils.java:108)
	at org.apache.flink.client.cli.CliFrontend.executeProgram(CliFrontend.java:1026)
	at org.apache.flink.client.cli.CliFrontend.run(CliFrontend.java:247)
	at org.apache.flink.client.cli.CliFrontend.parseAndRun(CliFrontend.java:1270)
	at org.apache.flink.client.cli.CliFrontend.lambda$mainInternal$10(CliFrontend.java:1367)
	at org.apache.flink.runtime.security.contexts.NoOpSecurityContext.runSecured(NoOpSecurityContext.java:28)
	at org.apache.flink.client.cli.CliFrontend.mainInternal(CliFrontend.java:1367)
	at org.apache.flink.client.cli.CliFrontend.main(CliFrontend.java:1335)
Caused by: org.apache.flink.table.api.TableException: Could not instantiate the executor. Make sure a planner module is on the classpath
	at org.apache.flink.table.api.bridge.internal.AbstractStreamTableEnvironmentImpl.lookupExecutor(AbstractStreamTableEnvironmentImpl.java:109)
	at org.apache.flink.table.api.bridge.java.internal.StreamTableEnvironmentImpl.create(StreamTableEnvironmentImpl.java:110)
	at org.apache.flink.table.api.bridge.java.StreamTableEnvironment.create(StreamTableEnvironment.java:122)
	at org.apache.flink.table.api.bridge.java.StreamTableEnvironment.create(StreamTableEnvironment.java:94)
	at FlinkCDC_SQL.main(FlinkCDC_SQL.java:27)
	at sun.reflect.NativeMethodAccessorImpl.invoke0(Native Method)
	at sun.reflect.NativeMethodAccessorImpl.invoke(NativeMethodAccessorImpl.java:62)
	at sun.reflect.DelegatingMethodAccessorImpl.invoke(DelegatingMethodAccessorImpl.java:43)
	at java.lang.reflect.Method.invoke(Method.java:498)
	at org.apache.flink.client.program.PackagedProgram.callMainMethod(PackagedProgram.java:355)
	... 9 more
Caused by: org.apache.flink.table.api.ValidationException: Multiple factories for identifier 'default' that implement 'org.apache.flink.table.delegation.ExecutorFactory' found in the classpath.

Ambiguous factory classes are:

org.apache.flink.table.planner.delegation.DefaultExecutorFactory
org.apache.flink.table.planner.loader.DelegateExecutorFactory
	at org.apache.flink.table.factories.FactoryUtil.discoverFactory(FactoryUtil.java:632)
	at org.apache.flink.table.api.bridge.internal.AbstractStreamTableEnvironmentImpl.lookupExecutor(AbstractStreamTableEnvironmentImpl.java:106)
	... 18 more
[qcln@hadoop102 flink-1.19.3]$
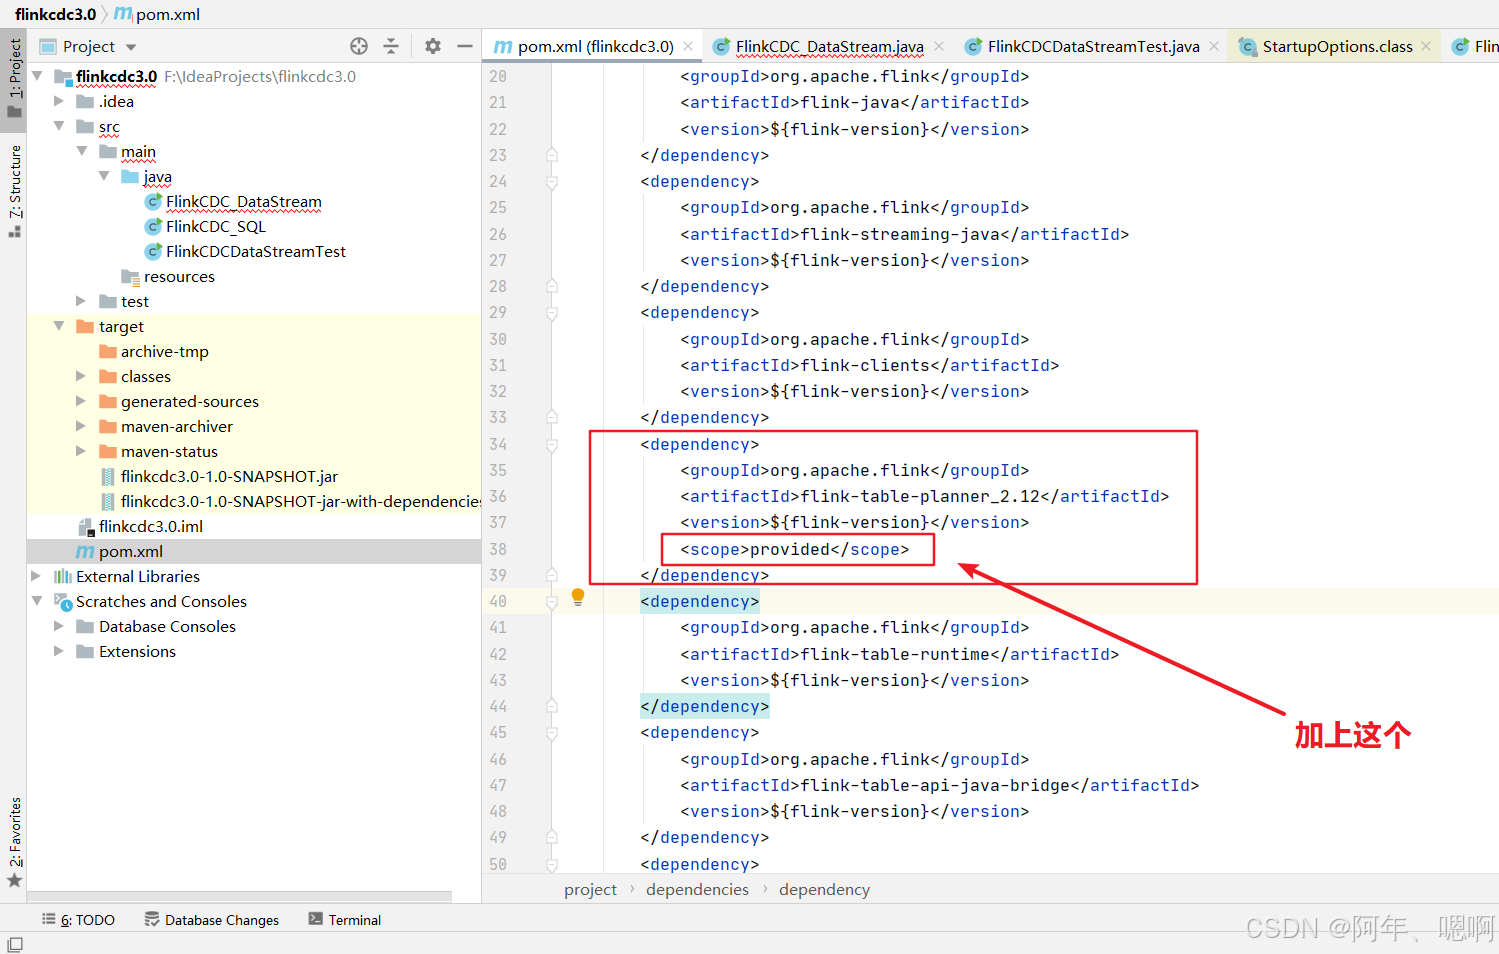
因为我打包的时候有个flink-table-planner_2.12依赖也打进去了,而我的flink-1.19.3环境里面本来就有一个,所以冲突了,把这个打包的时候不打进去就可以了
加上这个后,重新打包上传就行
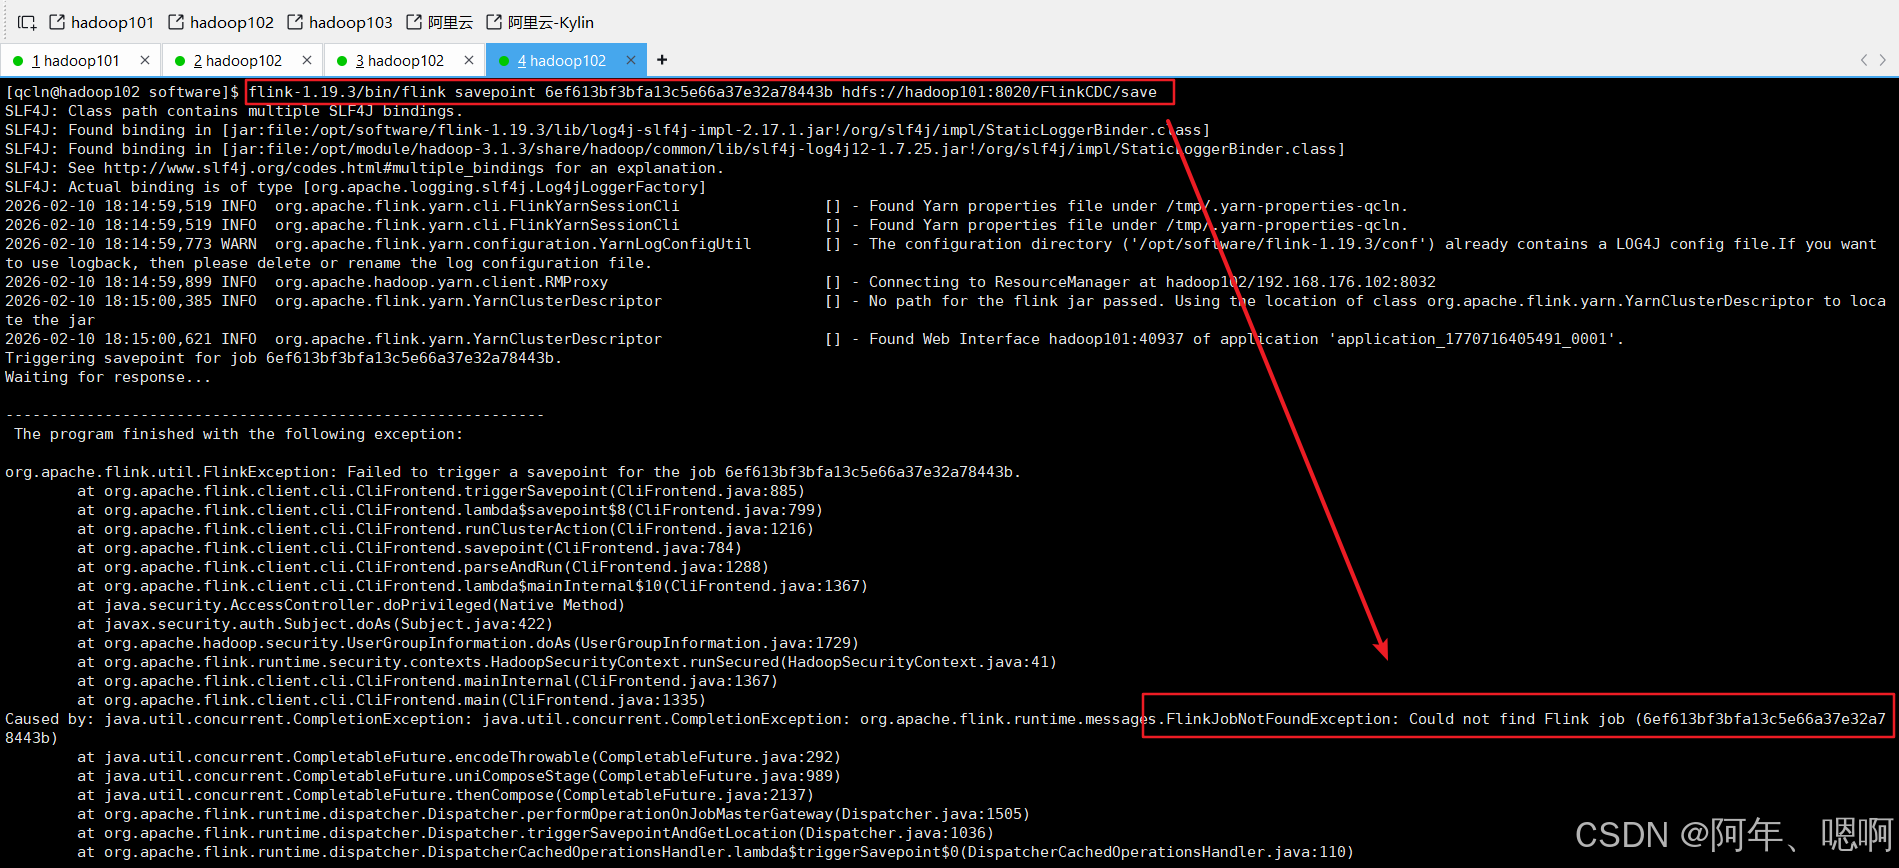
3. Could not find Flink job (6ef613bf3bfa13c5e66a37e32a78443b)
因为这个任务再Hadoop101机器的Task Manager上,我在hadoop102执行,报找不到这个job,去hadoop101上执行就好了
标准状态后端
import com.ververica.cdc.connectors.mysql.source.MySqlSource;
import com.ververica.cdc.connectors.mysql.table.StartupOptions;
import com.ververica.cdc.debezium.JsonDebeziumDeserializationSchema;
import org.apache.flink.api.common.eventtime.WatermarkStrategy;
import org.apache.flink.api.common.restartstrategy.RestartStrategies;
import org.apache.flink.api.common.time.Time;
import org.apache.flink.runtime.state.hashmap.HashMapStateBackend;
import org.apache.flink.streaming.api.CheckpointingMode;
import org.apache.flink.streaming.api.datastream.DataStreamSource;
import org.apache.flink.streaming.api.environment.CheckpointConfig;
import org.apache.flink.streaming.api.environment.StreamExecutionEnvironment;

import java.util.Properties;

public class FlinkCDCDataStreamTest {
    public static void main(String[] args) throws Exception {
        // TODO 1. 准备流处理环境
        StreamExecutionEnvironment env = StreamExecutionEnvironment.getExecutionEnvironment();
        env.setParallelism(1);

        // TODO 2. 开启检查点   Flink-CDC将读取binlog的位置信息以状态的方式保存在CK,如果想要做到断点续传,
        // 需要从Checkpoint或者Savepoint启动程序
        // 2.1 开启Checkpoint,每隔5秒钟做一次CK  ,并指定CK的一致性语义
        env.enableCheckpointing(3000L, CheckpointingMode.EXACTLY_ONCE);
        // 2.2 设置超时时间为 1 分钟
        env.getCheckpointConfig().setCheckpointTimeout(60 * 1000L);
        // 2.3 设置两次重启的最小时间间隔
        env.getCheckpointConfig().setMinPauseBetweenCheckpoints(3000L);
        // 2.4 设置任务关闭的时候保留最后一次 CK 数据
        env.getCheckpointConfig().enableExternalizedCheckpoints(
                CheckpointConfig.ExternalizedCheckpointCleanup.RETAIN_ON_CANCELLATION);
        // 2.5 指定从 CK 自动重启策略
        env.setRestartStrategy(RestartStrategies.failureRateRestart(
                3, Time.days(1L), Time.minutes(1L)
        ));
        // 2.6 设置状态后端
        env.setStateBackend(new HashMapStateBackend());
        env.getCheckpointConfig().setCheckpointStorage(
                "hdfs://hadoop101:8020/FlinkCDC/AutoRestart/ck"
        );
        // 2.7 设置访问HDFS的用户名
        System.setProperty("HADOOP_USER_NAME", "qcln");

        // TODO 3. 创建 Flink-MySQL-CDC 的 Source
		// initial:Performs an initial snapshot on the monitored database tables upon first startup, and continue to read the latest binlog.
// earliest:Never to perform snapshot on the monitored database tables upon first startup, just read from the beginning of the binlog. This should be used with care, as it is only valid when the binlog is guaranteed to contain the entire history of the database.
// latest:Never to perform snapshot on the monitored database tables upon first startup, just read from the end of the binlog which means only have the changes since the connector was started.
// specificOffset:Never to perform snapshot on the monitored database tables upon first startup, and directly read binlog from the specified offset.
// timestamp:Never to perform snapshot on the monitored database tables upon first startup, and directly read binlog from the specified timestamp.The consumer will traverse the binlog from the beginning and ignore change events whose timestamp is smaller than the specified timestamp.
                MySqlSource<String> mySqlSource = MySqlSource.<String>builder()
                .hostname("192.168.1.11")
                .port(3306)
                .databaseList("test ") // set captured database
                .tableList("test.a") // set captured table
                .username("root")
                .password("xxxxxx")
                .deserializer(new JsonDebeziumDeserializationSchema()) // converts SourceRecord to JSON String
                .startupOptions(StartupOptions.initial())
                .build();

        // TODO 4.使用CDC Source从MySQL读取数据
        DataStreamSource<String> mysqlDS =
                env.fromSource(
                        mySqlSource,
                        WatermarkStrategy.noWatermarks(),
                        "MysqlSource");

        // TODO 5.打印输出
        mysqlDS.print();

        // TODO 6.执行任务
        env.execute();
    }
}
更多推荐



 24
 0
- 0


 已为社区贡献7条内容

所有评论(0)